A runtime LLM denies admission to maintain 33 ms
Le brief IA que les pros lisent chaque soir
Les 7 actus IA du jour, décryptées en 5 min. Gratuit.
Inclus dès l'inscription : notre sélection des meilleurs guides & comparatifs IA.
Choisis ton rythme
Gratuit · Pas de spam · Désabonnement en 1 clic
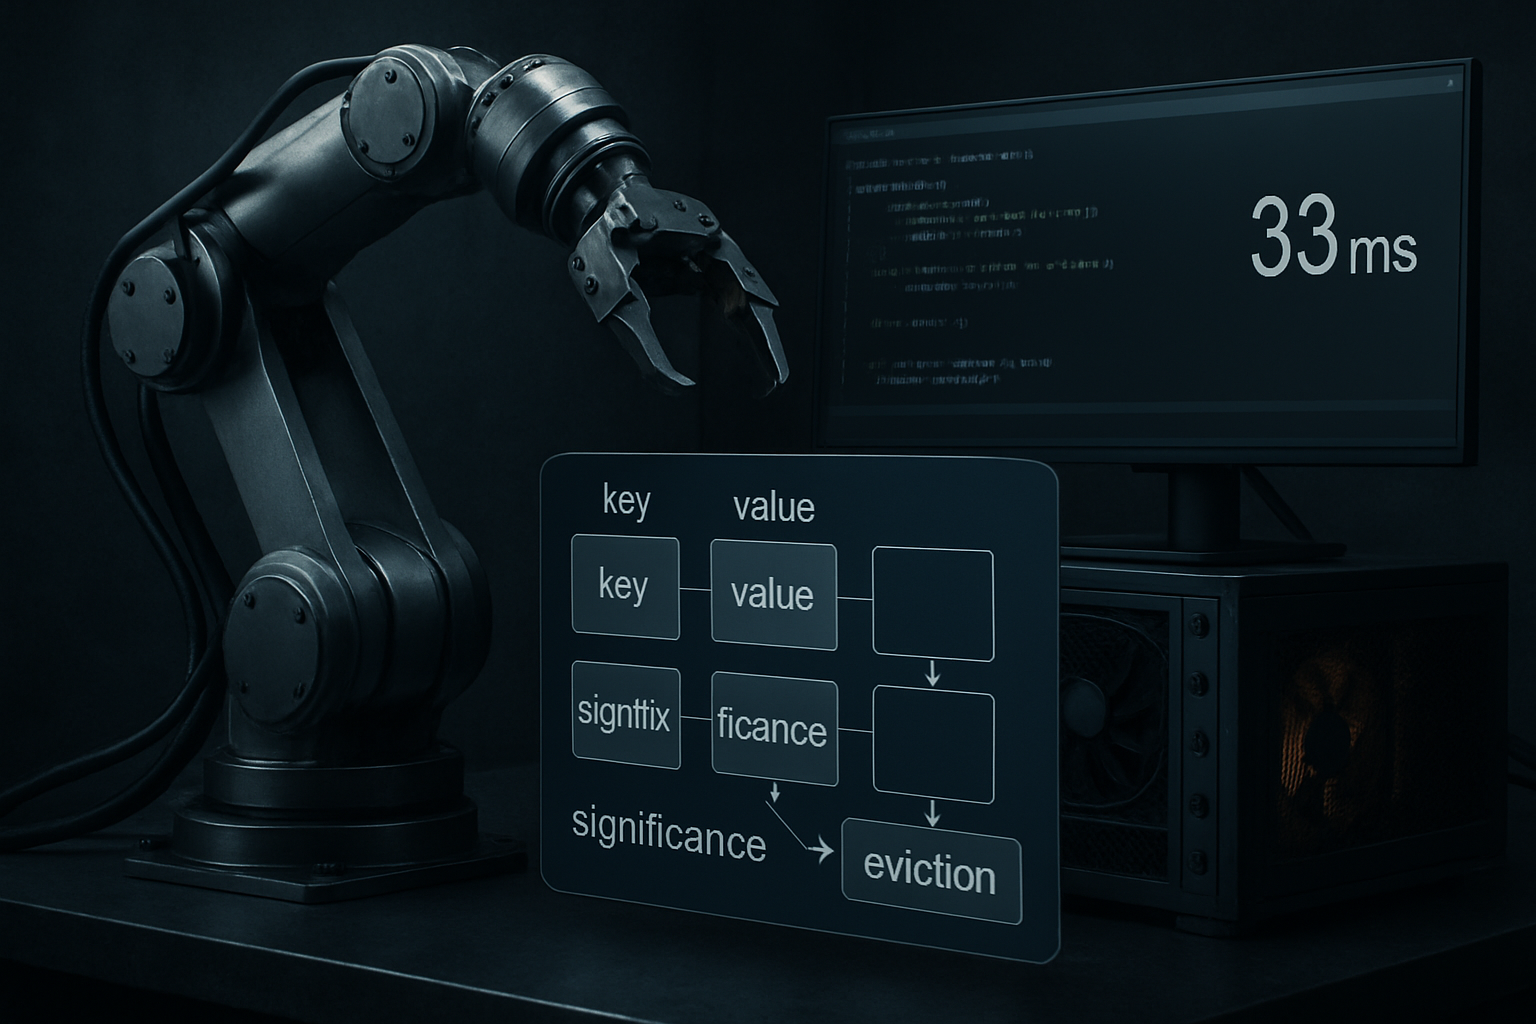
An inference engine for language models operates based on real-time principles. It prioritizes admission rejection to avoid exceeding a robotic control cycle of 33 ms, evicts its KV cache based on significance, and relies on manually developed CUDA code, without using cuBLAS or libtorch. Most inference solutions for LLMs do not consider the notion of physical deadlines.
Handcrafted CUDA and Significance-Based Cache Management
The runtime is entirely written in handcrafted CUDA, without resorting to cuBLAS or libtorch. It utilizes a KV cache whose eviction is based on the significance of the inputs, rather than their age.
Admission Rejection to Respect the 33 ms Robotic Cycle
This execution engine chooses to reject admission rather than risk exceeding a robotic control cycle of 33 ms. This method stands out from most inference engines for large language models (LLMs), which do not take into account any physical deadline constraints.
Brief IA — L'actualité IA en français
L'essentiel de l'actualité de l'intelligence artificielle, décrypté et expliqué chaque jour.