AI Agents: New Decision Models and Stated Limitations
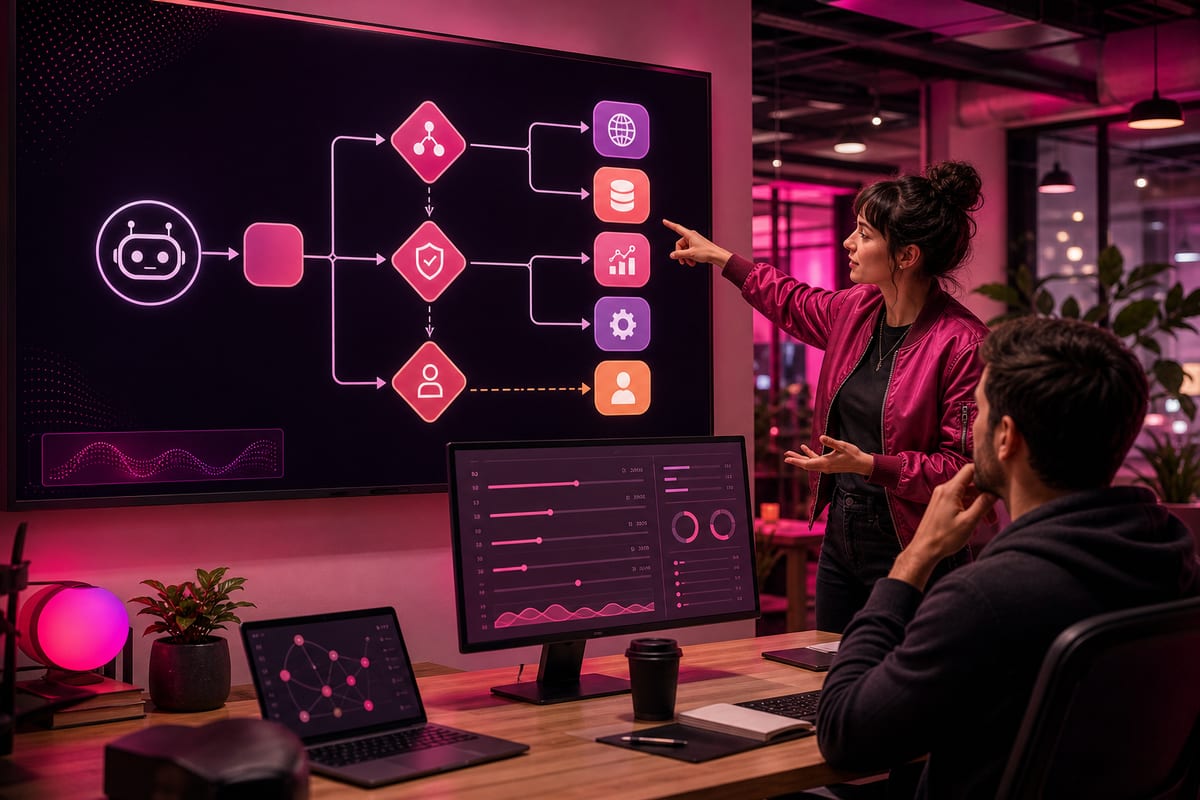
A new category of models focuses on the unitary decisions of agents, from routing to escalation, without generating text. Cloudflare, AWS, and OpenAI have rolled out their offerings following Jev from TypeSafe AI, while Anthropic adjusts cost parameters with Claude Haiku 5.5. Adoption figures exist, but the promised gains require caution.
The Promised Figures Remain to be Confirmed
Players in this segment present arguments for improvements in speed and cost, but it is important to approach these figures with caution. TypeSafe claims that, for a unique scenario developed and executed internally, its model would cost 444.6 times less and operate 193.6 times faster than a workflow relying on an LLM, without any independent verification having been conducted. Furthermore, at TypeSafe, the term "zero hallucinations" means only that the output matches the expected schema, without guaranteeing the correctness of the decision. Compliance with the schema is a prerequisite, but it is not sufficient to ensure the quality of a decision.
Three Recurring Decisions, Without the Need for Prose
Agent loops rely on three types of repeated decisions: choosing which tool or sub-agent to activate, deciding whether a check should allow or block an input, and determining whether a case should be handled automatically or passed to a more complex model or a human. These decisions do not require text generation, but rather a selection from known options, in the form of a label, score, or binary response. Historically, generalist LLMs were used for these tasks, through adapted prompts, but this method was not the most efficient. Not all of these decisions necessarily require a dedicated model or a complete reasoning model. The choice of model depends on three questions: does the input correspond to a closed set of options or does it require synthesizing new information? Is the decision frequent enough for the savings per call to become significant? And what are the consequences of an incorrect decision?
Le brief IA que les pros lisent chaque soir
Les 7 actus IA du jour, décryptées en 5 min. Gratuit.
Inclus dès l'inscription : notre sélection des meilleurs guides & comparatifs IA.
Choisissez votre rythme
Gratuit · Pas de spam · Désabonnement en 1 clic
After Jev, Cloudflare, AWS, and OpenAI Join the Dance
In September, TypeSafe AI launched Jev, a model that does not generate text but evaluates typed questions in a single pass and returns a choice, score, or probability with calibrated confidence. TypeSafe presents it as a "System One" model, designed for narrow routing or filtering steps. In the following weeks, three other providers launched their own models. Cloudflare released Clef and Clef-flash as open source on October 1, under the Apache 2.0 license and on Workers AI, with Clef also accepting image and video inputs. On the same day, AWS announced Strands Decider 2B, an open-source model of about 2 billion parameters based on Qwen3.5, designed to run locally in under 150 milliseconds. On October 6, OpenAI made available the Decisions API, based on GPT-6 Luna, which, according to the company, delivers decisions up to 10 times faster than the general Responses API.
A Signal of Adoption from Vercel
Jev quickly attracted attention. According to Vercel, within 24 hours of its listing on AI Gateway, nearly 13% of paying teams tested the model, which is more than double the adoption rate observed during any previous model launch on the platform. This adoption dynamic is explained by the visibility and ease of access to cost for developers.
Anthropic Adjusts Costs with Haiku 5.5
Anthropic has not announced a decision-specific model like Jev, Clef, or Strands Decider. On October 7, the company launched Claude Haiku 5.5, which reduces the price for prompts of less than 100,000 tokens to $0.10 per million input tokens and $0.50 per million output tokens, down from $1 and $5 previously. Haiku 5.5 also offers an effort adjustment, allowing the level of reasoning to be modulated with each request, rather than treating latency and cost as constants.
Brief IA — L'actualité IA en français
L'essentiel de l'actualité de l'intelligence artificielle, décrypté et expliqué chaque jour.