Cloudflare: Blocking AI Training Without Losing Google
Le brief IA que les pros lisent chaque soir
Les 7 actus IA du jour, décryptées en 5 min. Gratuit.
Inclus dès l'inscription : notre sélection des meilleurs guides & comparatifs IA.
Choisis ton rythme
Gratuit · Pas de spam · Désabonnement en 1 clic
Cloudflare is implementing fine control to refuse model training without disrupting indexing by engines that meet "Accountable" criteria. The options apply at the domain level, automatically migrating for existing sites, and are part of a trajectory that includes an AI summary adjustment planned for early 2027.
A Control Designed to Last, with a Target Set for Early 2027
Cloudflare plans to introduce a unique platform-side adjustment by early 2027 to control the amount of content included in AI-generated summaries, eliminating the need to negotiate separately with each operator. Currently, the Block setting extends to mixed crawlers and also blocks access from Applebot, Bingbot, and Googlebot, including for search. Additionally, the option to refuse AI summaries via Cloudflare is set to be announced for 2027.
Domain-Level Configuration and Migration Without Action
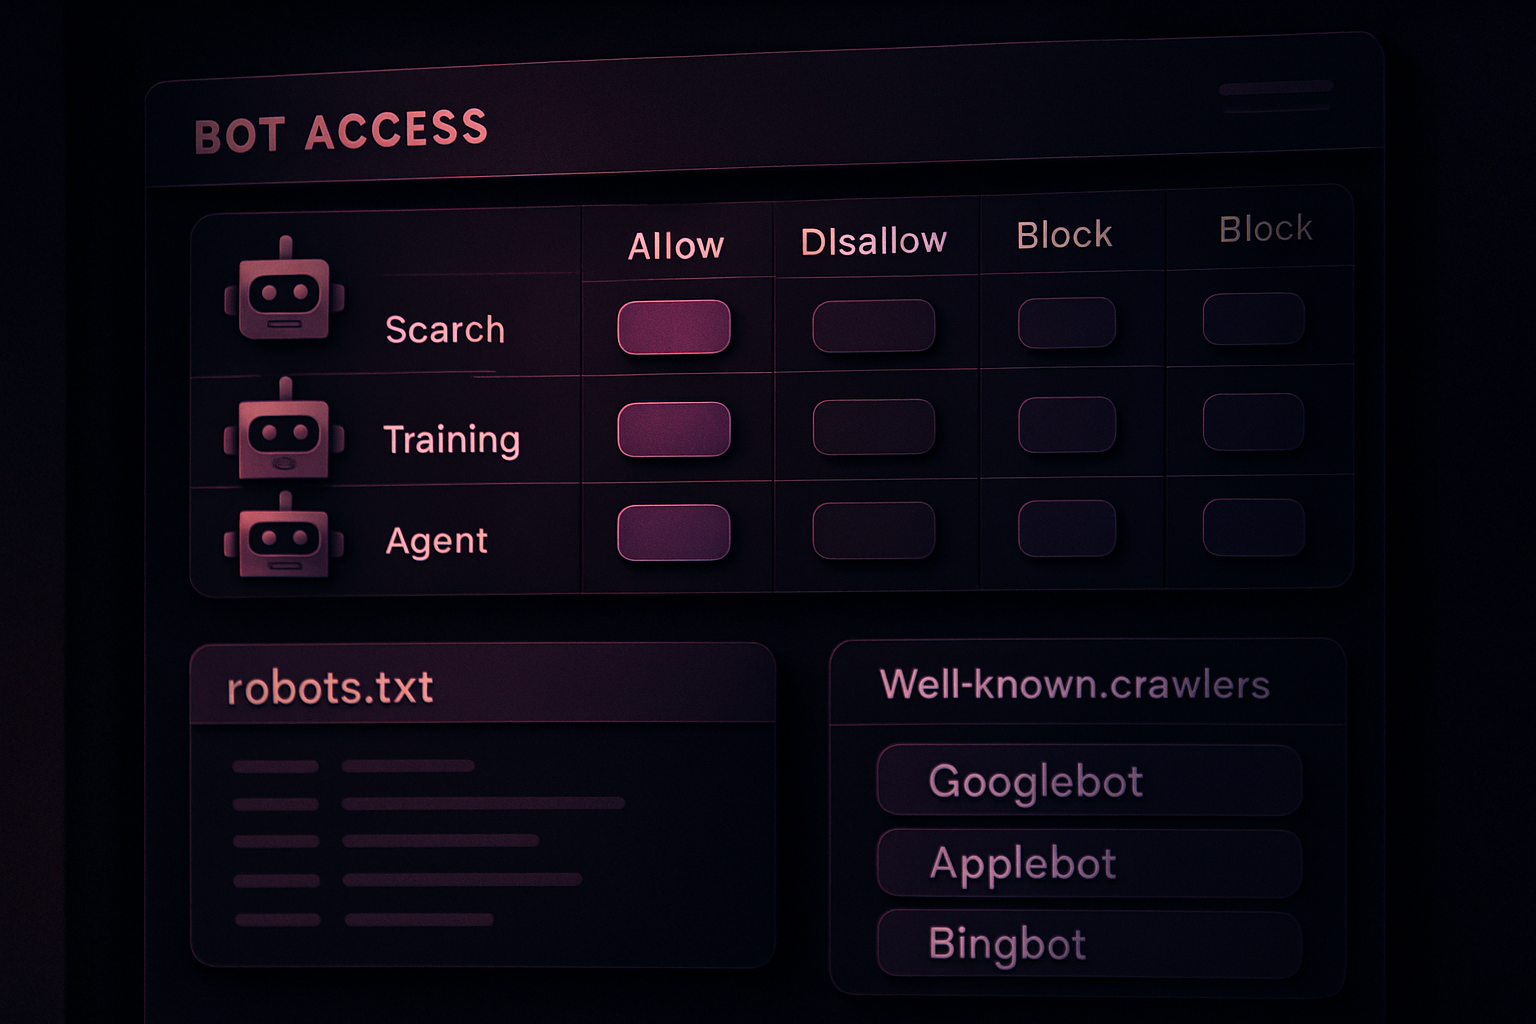
The changes pertain to Bot Management as well as AI Crawl Control. The control options, available for all plans, apply at the domain level through the security settings in the dashboard. Cloudflare identifies three types of bot behaviors: Search for indexing, Training for model training, and Agent for user-requested agents. Four configuration options are available: Allow, Disallow AI Training which applies only to the Training behavior, Block on pages with ads which targets only pages containing detected ads, and Block which prevents access for all concerned bots. Sites that are already configured do not need to take any action: their current settings are automatically preserved. When a domain is set to Block or Block on pages with ads for training, it is automatically switched to Disallow AI Training. If the Block AI Bots option was previously used on a domain, it changes to Allow for Search, Disallow AI Training for Training, and Block on pages with ads for Agent. For new domains, two predefined configuration options are available: sites funded by advertising are assigned Disallow AI Training for Training and Block on pages with ads for Agent, while others retain Allow on all three parameters.
Who Remains Indexed and Under What "Accountable" Conditions
The "Accountable" status is granted to operators who meet or commit to meeting four conditions: providing an option to refuse training via robots.txt or an equivalent solution; offering the ability to refuse the use of AI summaries with the operator; allowing visibility at the URL level regarding pages accessible for training, accompanied by statistics on how the content appears in search results; and ensuring that refusing training does not impact traditional SEO. Apple, Google, and Microsoft meet these requirements through already deployed features and dated commitments for the remaining aspects. For these companies classified as "Accountable," indexing remains permitted even in the case of a training refusal. The Disallow AI Training setting adds a specific refusal instruction for each operator in the site's robots.txt file.
Mechanisms by Engine: Google-Extended, Applebot-Extended, and Bing's Trajectory
At Google, the training refusal directive is enforced using a Disallow rule on Google-Extended; at Apple, the same instruction is implemented via Applebot-Extended. Microsoft still needs to integrate the management of a non-training preference in the robots.txt file, an evolution expected in early 2027; until then, activating Disallow AI Training does not convey any information to Bing, whose training deactivation relies on the NOARCHIVE tag. The bots used for training by Amazon, Anthropic, Meta, and OpenAI, which are separate from their search bots, continue to be blocked. According to Cloudflare, less than 1% of the sites it protects choose to block search bots, while 17% activate a training blocking mechanism.
Another Milestone in Crawl and Agent Management
This announcement is part of a series of initiatives by Cloudflare surrounding crawling and AI. The company has notably trapped training bots in pages generated with AI Labyrinth, launched the "Pay per Crawl" payment model, offered to automatically serve a Markdown version of pages to agents, and opened an endpoint allowing exploration of an entire site in a single API request.
Brief IA — L'actualité IA en français
L'essentiel de l'actualité de l'intelligence artificielle, décrypté et expliqué chaque jour.