Evaluating LLMs: A Modular Python Framework in 4 Modules
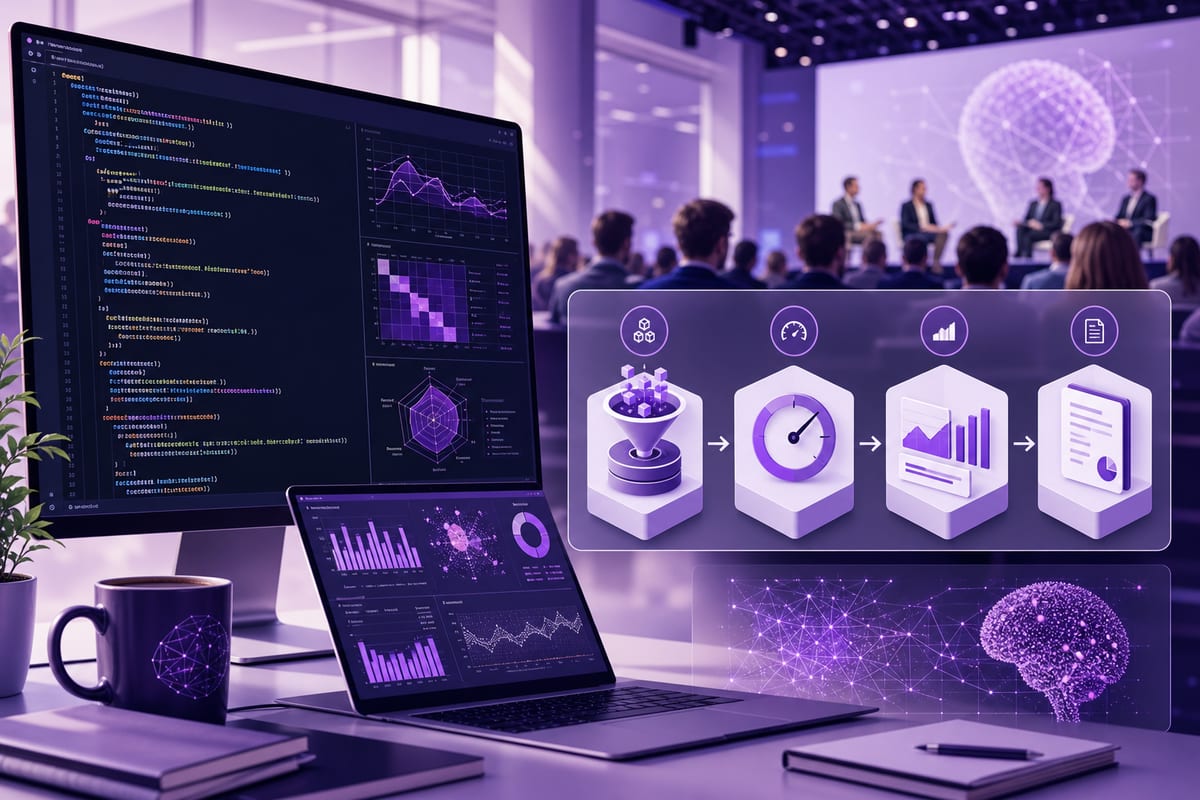
A language model evaluation framework in Python, structured around four modules, aims to combine standardized metrics with criteria tailored to specific use cases. It has received a positive reception and could, if widely adopted, bring evaluation practices closer among stakeholders.
Towards Favorable Adoption and Possible Standardization
The reception of customized evaluation frameworks is described as generally positive. Artificial intelligence specialists emphasize the need for tools that cater to the specificities of language models, and forums as well as conferences highlight this approach. In the long term, other organizations, including competing companies, may develop their own systems. This dynamic could lead to a standardization of evaluation practices, facilitating comparisons between different models and approaches.
Four Python Modules to Structure Evaluation
This framework relies on a modular structure in Python, designed to be adjustable according to the specifics of each project. It consists of four essential modules: one dedicated to data preprocessing, another for performance evaluation, a third for result visualization, and a final one for automatic report generation. The preprocessing module is responsible for optimizing the input data intended for the model being tested, while the entire system allows for model evaluation based on both standard and application-specific criteria.
Le brief IA que les pros lisent chaque soir
Les 7 actus IA du jour, décryptées en 5 min. Gratuit.
Inclus dès l'inscription : notre sélection des meilleurs guides & comparatifs IA.
Choisis ton rythme
Gratuit · Pas de spam · Désabonnement en 1 clic
Metrics Used and Reported Reliability Gains
To measure the performance of language models, the evaluation module relies on established indicators such as perplexity and the BLEU score. According to several studies, using customized evaluation frameworks could increase model reliability by 20 to 30%. This gain is considered particularly significant in fields such as healthcare, finance, or education, where the accuracy of models is crucial.
Quality, Transparency, and Usage Requirements
Companies implementing such tools may see the quality of their products improve, which can lead to increased customer satisfaction and a reduction in risks associated with decisions based on faulty models. This evaluation framework can also promote the transparency of language models by providing readable and accessible results that facilitate the justification of technological choices and enhance user trust. In a context of growing ethical and regulatory concerns, developers and researchers are encouraged to share their feedback and contribute to the continuous improvement of the framework. The need for rigorous and tailored evaluations is expected to intensify with the evolution and integration of language models, and the creation of such a framework is presented as a major challenge for the future of artificial intelligence.
Brief IA — L'actualité IA en français
L'essentiel de l'actualité de l'intelligence artificielle, décrypté et expliqué chaque jour.