Fable 5.2 Hits 41.3% on Real Missions and Takes the Lead
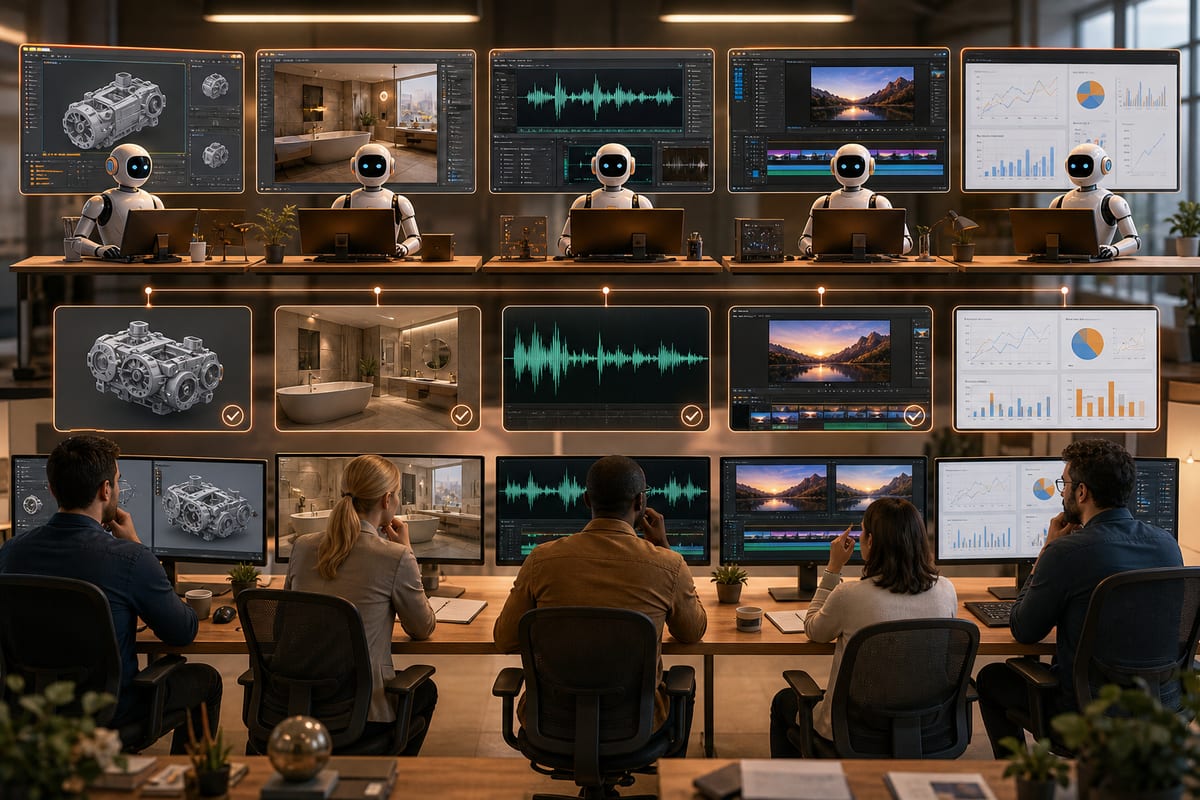
A testing bench based on 240 Upwork projects and human verification places Fable 5.2 at the top with 41.3% of tasks delivered at a professional level. The gap with its predecessors and rivals is clear, although the organizers still report blind spots depending on the types of tasks.
A protocol on real tasks and mandatory human review
The Remote Labor Index evaluates complete tasks rather than isolated skills. The corpus includes 240 projects conducted by 358 verified professionals on Upwork, valued at approximately $144,000. On average, a project costs $632.60 and engages a human freelancer for just under 29 hours. The tasks cover video editing, CAD design, game development, and data analysis. AI agents operate in a virtual space equipped with software such as Blender, GIMP, or Audacity, as well as tools for generating images, audio, and video. Examples include producing a floor plan, furniture options, and photorealistic renders of bathrooms.
Validation relies on human experts who open the deliverables in the relevant software and compare them to the work produced by the freelancer. Attempts by CAIS to automate this review have, so far, failed. CAIS mentions automatic evaluators that are unable to properly utilize professional software, vulnerable to visually polished but technically flawed submissions, and overly generous in their ratings. The index thus measures the frequency with which an agent delivers an outcome accepted by a paying client.
Current ranking: Fable 5.2 ahead of Opus 5.5 and GPT 6 Astra
Fable 5.2 holds the top position in the Remote Labor Index with 41.3%. It is followed by Opus 5.5 from Anthropic at 21.25% and GPT 6 Astra from OpenAI at 20.83%. Google’s best model in this test, Gemini Argon 4, ranks fifth with 17.08%, while older versions like GPT-5.2 or Gemini 3 Pro remain below 3%. Fable 5.2 operates almost twice as efficiently as its pursuers. These results confirm an advantage over its direct predecessor and other evaluated players.
Le brief IA que les pros lisent chaque soir
Les 7 actus IA du jour, décryptées en 5 min. Gratuit.
Inclus dès l'inscription : notre sélection des meilleurs guides & comparatifs IA.
Choisissez votre rythme
Gratuit · Pas de spam · Désabonnement en 1 clic
An acceleration in a few months compared to previous models
In July, Fable 5 was still leading with around 16%, after an eight-month period during which the share of tasks delivered at a professional level by the best agents had more than quadrupled. Four months later, Fable 5.2 shows a rate of 41.3%, which represents about two and a half times the performance of Fable 5 in July. The immediate previous version, Fable 5.1, is just below 18%, while Fable 5.2 achieves more than double that. The contrast with the early days of the benchmark is striking: at launch, the best system, Manus, did not exceed 2.5% of tasks, a level that Fable 5.2 now surpasses by more than 16 times. Overall, Fable 5.2 completes over 41% of projects with quality deemed professional.
Strengths in audio, 3D, and architecture; limitations in products and animation
Scale Labs reports the strongest advancements of Fable 5.2 in audio and music editing, architectural and interior design, as well as 3D modeling. The agent also handles long and complex projects that previously better-rated systems failed to complete. Nearly 50 of its successes involve tasks that no agent had yet resolved in this test. At the same time, Scale Labs indicates persistent difficulties in industrial product design and animation. Researchers describe, in cases of failure, deliverables that appear amateurish, incomplete results, corrupted files, or inconsistent designs.
Brief IA — L'actualité IA en français
L'essentiel de l'actualité de l'intelligence artificielle, décrypté et expliqué chaque jour.