Humanizer Open Source: Inconsistent Local Detection
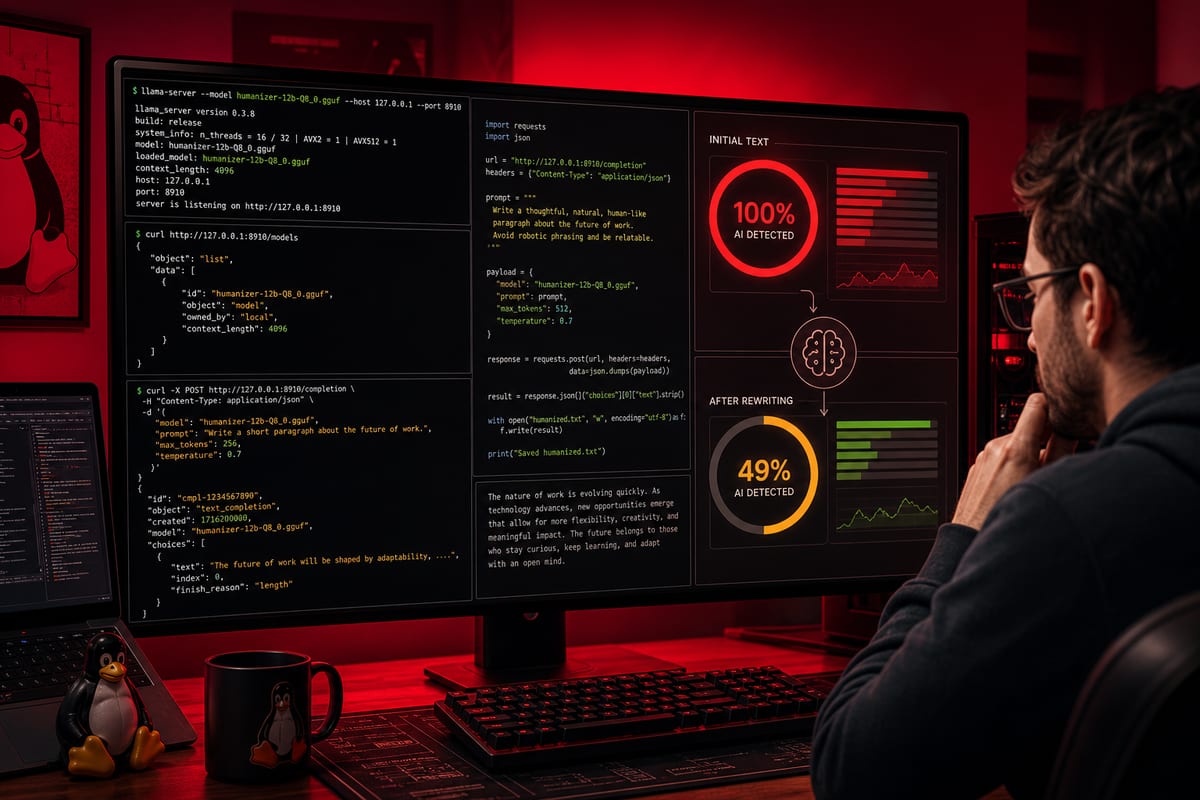
Humanizer offers a way to locally rewrite text generated by AI, without a subscription or sending data to a third-party service. The developer claims high scores against Originality.ai, while tests describe fluctuating results depending on the content and detectors. The model runs on PC, with a dedicated application or through local inference engines.
Tests Report Variable Results Against Detectors
In a test involving an article of about 200 words initially deemed 100% AI-generated by GPTZero, rewriting via Humanizer reduced the detection rate to 49% and increased the human writing score to 51%. GPTZero remained uncertain, indicating that the text would likely be considered human. Trials on several AI-generated texts led to rankings deemed random by the test author, who estimates a 50% chance of obtaining a good result. Despite following the recommended instructions and parameters, these performances were not consistently reproduced compared to the claimed figures. Since AI detectors can produce false positives, evaluating the effectiveness of a "humanizer" based solely on their scores remains uncertain. The model may also introduce factual errors, and its results vary depending on the detectors.
High Promises Claimed by the Developer
The developer claims that 95% of the 210 rewrites in English were classified as human by Originality.ai. They attribute about 93% to the quantized version Q8_0. These performances have not been independently verified. The figures presented describe significant circumvention capability but remain statements from the developer.
Model Design and Training Choices
Humanizer is based on a Gemma 4 12B foundation and totals 12 billion parameters. It has been fine-tuned to rewrite AI-generated texts in a more natural style, aiming to preserve meaning and facts. Its training includes 28,598 AI-to-human pairs from academic articles, government reports, emails, and platforms like Reddit and Hacker News. After supervised fine-tuning, the developers applied Direct Preference Optimization with 3,918 pairs, followed by Group Relative Policy Optimization, a LLM evaluating rewrites based on factual accuracy, unnecessary copying, and changes in meaning. No AI detectors were employed during the training phase, prioritizing writing quality and factual consistency. During generation, the model modifies sentence structure, eliminates typical AI repetitions, varies sentence length, and strives to retain the original information.
Le brief IA que les pros lisent chaque soir
Les 7 actus IA du jour, décryptées en 5 min. Gratuit.
Inclus dès l'inscription : notre sélection des meilleurs guides & comparatifs IA.
Choisissez votre rythme
Gratuit · Pas de spam · Désabonnement en 1 clic
Local Execution: Application, Supported Engines, and Quantization
Humanizer can operate locally without a subscription or API calls, either through a desktop application for Windows and macOS that can be used offline, or via inference engines such as llama.cpp, Ollama, Transformers, MLX, or vLLM. llama.cpp allows for running LLMs locally via an HTTP API exposed by llama-server. The quantized 8-bit version Q8_0 is available and presented as a compromise between quality and memory, with quantization reducing hardware requirements. However, Q8_0 requires substantial VRAM, and a humanizer-12b-Q6_K variant is suggested for more limited GPUs. The local server notably publishes the /completion and /models endpoints.
Typical Setup with llama.cpp and Recommended Parameters
On Linux with NVIDIA CUDA, llama.cpp can be compiled with GPU acceleration after retrieving the repository. The construction of llama-server can be verified via the --version option, with an example displaying built with GNU 13.3.0 for Linux x86_64. The weights and prompt format are obtained with the Hugging Face client, then the server is launched by loading the .gguf file and binding the host to 127.0.0.1. Options allow for offloading layers to the GPU, setting a context window to 8192, and enabling Flash Attention. The service listens locally on port 8910, with a /models endpoint to check loading. A draft of about 200 words is placed in draft.txt, and in the humanize.py script, the official prompt is concatenated to the text before sending it to /completion. Parameters include temperature set to 1.0, repeat_penalty at 1.0, n_predict at 2048, and a top_p of 0.95, in line with the mentioned recommendations. The JSON request defines a timeout of 600 seconds, and the result is saved in humanized.txt. The article used for the test dealt with the local execution of AI models and had initially been detected as 100% AI-generated by GPTZero.
Community Adoption and Scope of Use
As of early October 2026, Humanizer has accumulated over 143,000 downloads and 2,100 likes on Hugging Face. Its local execution, without a subscription or API call, makes it an accessible option for rewriting texts while keeping data on the user's machine.
Brief IA — L'actualité IA en français
L'essentiel de l'actualité de l'intelligence artificielle, décrypté et expliqué chaque jour.