HyperAccel Highlights Its LPU with 3.5x Efficiency per Watt
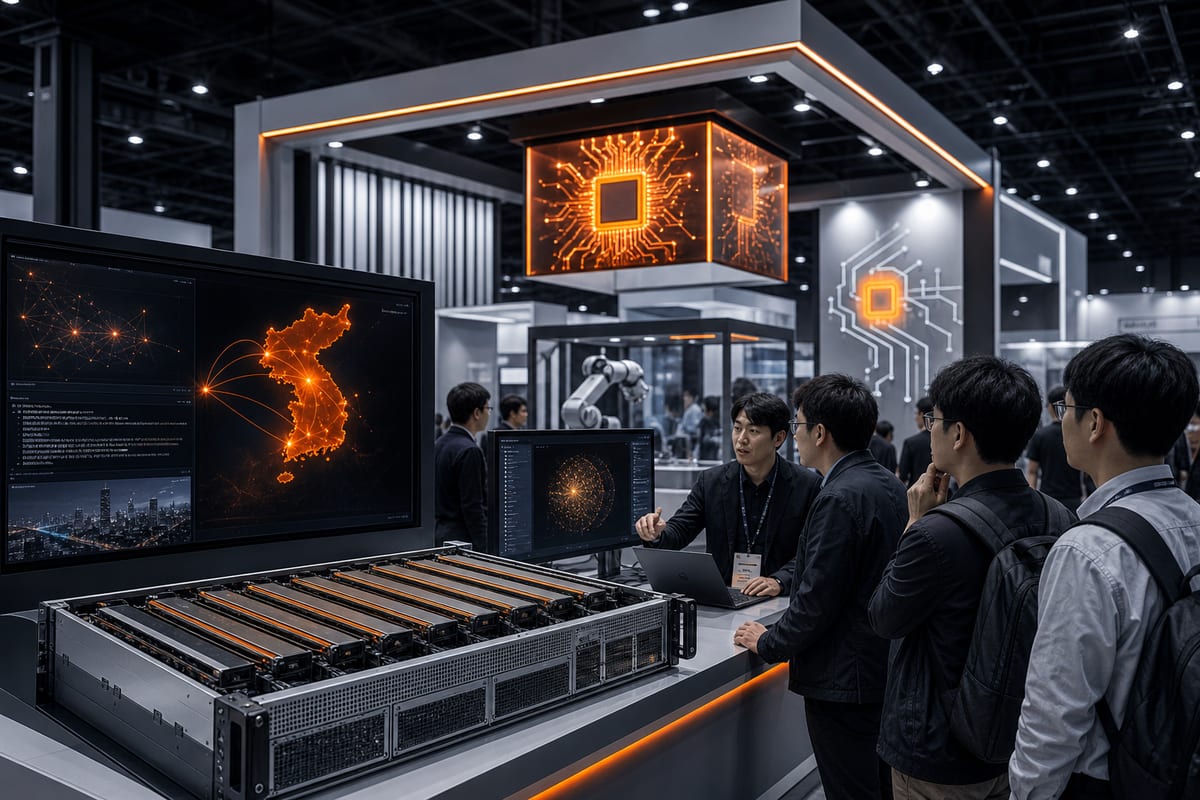
At SC26 in Chicago, HyperAccel aims to showcase a dedicated LPU architecture for LLM inference. The company highlights efficiency gains per watt and per dollar and is preparing a remote demonstration from Korea while seeking partners to deploy its technology in data centers.
HyperAccel Seeks Partnerships and Global Adoption of Its LPU
HyperAccel aims to strengthen its international presence and accelerate the adoption of inference infrastructures based on its LPU. The company is targeting partnerships with server manufacturers, cloud service providers, and AI infrastructure players. Announced priorities include integrating server platforms, technical validation, and commercial development in global data center markets. According to CEO Joo-Young Kim, the industry is now shifting towards efficiency and cost-effectiveness in large-scale AI inference, beyond just raw performance. He claims that the LPU architecture enables superior token efficiency at the server level, reducing costs and energy consumption, and seeks to collaborate with global infrastructure partners to market more efficient and scalable AI solutions.
Claimed Performance Superior to Blackwell GPUs
Internal tests conducted by HyperAccel indicate that a server equipped with LPU cards consuming 250 W each would deliver a token throughput more than 3.5 times greater per watt and per dollar compared to an equivalent setup with NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs consuming 600 W per card, when using the Qwen3-32B and Llama3-70B models. HyperAccel also states that its LPU is compatible with larger LLM models, such as Kimi and GLM. Technically, the LPU combines low-power LPDDR5X memory with Streamlined Dataflow architecture. According to the company, this solution achieves about 90% memory bandwidth utilization, while GPUs range between 50% and 60%, which it claims helps reduce energy consumption and operating costs in large-scale inference environments.
Le brief IA que les pros lisent chaque soir
Les 7 actus IA du jour, décryptées en 5 min. Gratuit.
Inclus dès l'inscription : notre sélection des meilleurs guides & comparatifs IA.
Choisissez votre rythme
Gratuit · Pas de spam · Désabonnement en 1 clic
A Remote Demonstration and an Eight-LPU Server at the Exhibition
HyperAccel will showcase a server system integrating eight LPUs on-site. A live remote demonstration is set to show LLM inference executed on operational servers deployed in Korea. The exhibition aims to illustrate the functioning of the LPU at the server scale, beyond the individual component, to create a deployable AI infrastructure. Visitors will be able to learn about the technology, explore the eight-LPU server, and attend the remote demonstration to observe inference on production hardware and assess the potential for enterprise and data center deployments.
SC26 in Chicago: Dates, Locations, and Speaking Engagements
HyperAccel's presentation of the LPU technology is scheduled for SC26, held at McCormick Place in Chicago. The event will take place from November 17 to 19, 2026. The team will welcome visitors at the AI Semiconductor Korea Pavilion, booth #1411. Additionally, Joonyeon Kim, the company's CFO, will speak on November 18 from 2:30 PM to 2:45 PM (Central Time) at Lablup Inc.'s booth #4630, with a session titled "Redefining AI Infrastructure Through Token Efficiency."
Company Profile and Product Lines
Founded in 2023, HyperAccel is a South Korean AI semiconductor company without a factory, based in Seoul and present in Silicon Valley. It develops LPUs, accelerators designed for large language model inference. Its product range includes Bertha, aimed at data centers and enterprises, as well as Bertha-Edge, designed for embedded artificial intelligence. HyperAccel also applies its technology to use cases involving edge computing and physical artificial intelligence. The company received the IEEE Micro Best Paper Award in 2025 and is listed in Forbes Asia 100 To Watch 2026. A press release is dated Chicago, November 13, 2026.
Brief IA — L'actualité IA en français
L'essentiel de l'actualité de l'intelligence artificielle, décrypté et expliqué chaque jour.