TypeSafe AI's Jev: Quick Decisions, Reduced Costs, Accuracy to Confirm
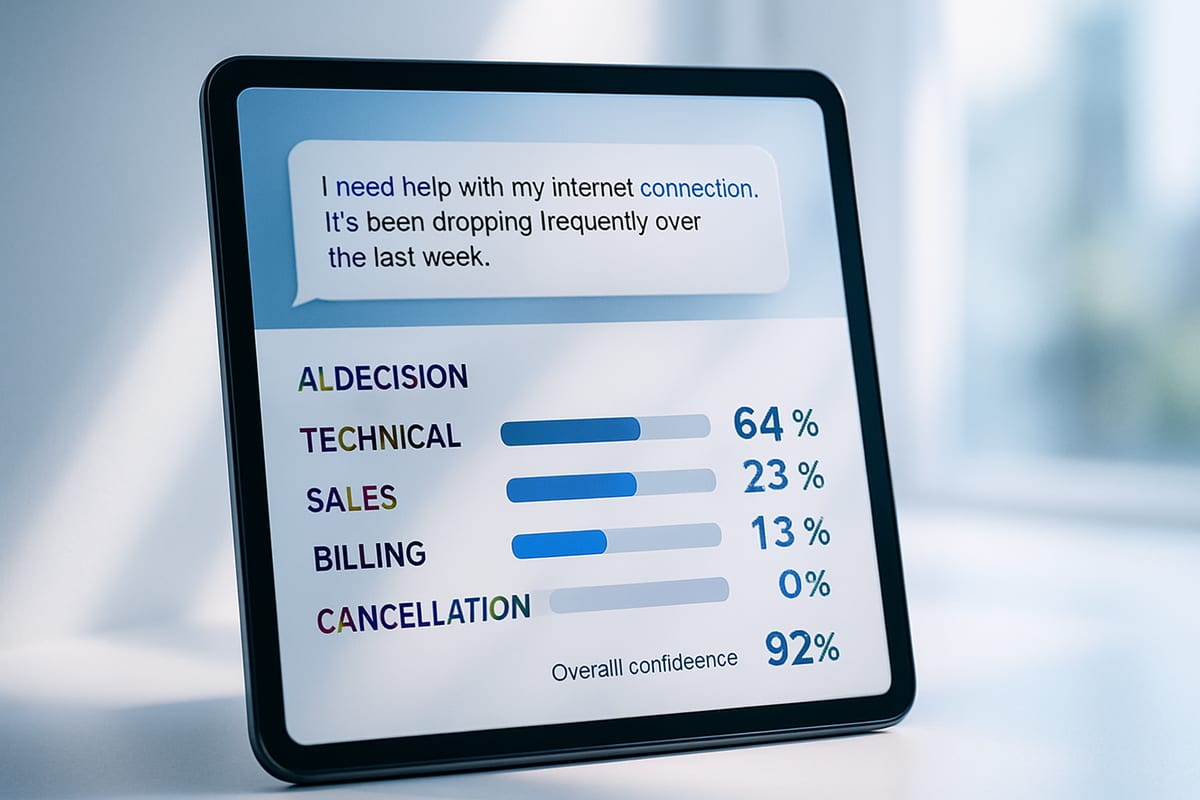
TypeSafe AI presents Jev as a "System One" model focused on structured decisions and calibrated probabilities. Initial feedback praises its speed and cost, while the publisher claims a dedicated training method. However, the extent of independent evidence regarding its accuracy remains limited.
Public Evidence Remains Partial and From Limited Sources
Few detailed technical elements have been made public regarding Jev's architecture, training configuration, and size. Some of the claims about it rely on benchmarks provided by TypeSafe AI. The publisher indicates a score of around 68% on an internal workflow evaluation, with references coming from state-of-the-art models rather than independently verified truths. External tests exist but are limited: a small fact-checking trial reports 96.3% accuracy, and another evaluation on 275 documents observes strong agreement on certain tasks. However, these exercises remain restricted. The reported results are deemed promising but are insufficient to establish overall accuracy, and additional independent benchmarks are awaited.
Structured Decisions and Probabilities Rather Than Free Text
Jev is presented as a model dedicated to quick and structured decisions, distinct from generative models. TypeSafe AI refers to it as a System One model, returning a probability distribution over a fixed set of choices instead of a lengthy textual response. An example of a support ticket illustrates a distribution of 64% for Technical, 23% for Sales, 13% for Billing, and 0% for Cancellation, while also highlighting ambiguity. The probabilities guide practical usage, for instance, to automatically route or trigger a human review based on a confidence threshold. The approach focuses Jev on transforming text into decisions, with an overall confidence score distinct from the percentages by label.
Speed and Costs: Specialization and Parallel Inference
TypeSafe AI attributes Jev's speed and low cost to a specialized architecture, parallel sampling, and calibration-oriented training. The logic differs from versatile LLMs, which are costly when constrained for simple classification tasks. Precedents like facebook/bart-large-mnli already illustrate the interest in targeted models for lightweight zero-shot classification. In this context, it is expected that a specialized model classifies faster and cheaper than a state-of-the-art model, with the key issue being effective quality on the targeted tasks.
Le brief IA que les pros lisent chaque soir
Les 7 actus IA du jour, décryptées en 5 min. Gratuit.
Inclus dès l'inscription : notre sélection des meilleurs guides & comparatifs IA.
Choisissez votre rythme
Gratuit · Pas de spam · Désabonnement en 1 clic
RLCD: Probabilities Intended to Reflect Uncertainty
TypeSafe AI claims to train Jev with RLCD, or Reinforcement Learning for Calibrated Decisions. The goal is for the probabilities to align the displayed confidence with the actual correctness frequency. One example mentions percentages by category and an overall confidence score of 53%. With satisfactory calibration, high-confidence predictions should be correct more often. This property makes uncertainty exploitable in software, allowing automation beyond a threshold while escalating less certain cases. The publisher contrasts this approach with RLHF, which aims for responses preferred by human annotators.
Zero Out of Schema Does Not Mean Zero Errors
Jev does not generate categories outside the provided choices: faced with options like Billing, Technical, and Sales, it will not return Legal. However, it can make mistakes by selecting an inaccurate alternative among the proposed labels. The term "zero hallucination" is thus understood here as the absence of out-of-schema outputs, not as the complete absence of errors.
Tested Use Cases: Routing, Navigation, and Low-Cost Analytics
Targeted applications include repeated unit decisions such as routing, classification, scoring, or action choice by an agent. One user, blackbarata, reports routing between specialized agents in 145 to 271 milliseconds. Another, TigerOk4538, measures about 1 second for Jev compared to 4 to 14 seconds for a structured LLM. Browser Use has designed jev-ultrafast, where Jev selects action and browser element; a demonstration on Google Flights lasted about 7.1 seconds. Matthew Berman mentions analyzing 724 ads from 37 brands in about 40 seconds, for a cost close to $0.09. These feedbacks describe Jev as a decision layer integrated into larger systems rather than as a final answer generator.
Positioning Against LLMs and Zero-Shot Classifiers
The tasks handled by Jev, such as classification or intent detection, have been established for a long time. TypeSafe AI claims a dedicated approach, described within the System One/Two framework, which contrasts quick decisions with deliberative reasoning. The author relates Jev to zero-shot classification, popularized in its NLI form around 2019-2020, while emphasizing that TypeSafe AI focuses on multiple decisions, parallel inference, and calibration. Jev is not positioned alongside generalist models like GPT, Claude, or Gemini, which target coding, reasoning, tools, and open generation. The central question becomes the quality proximity on narrow tasks to consider replacements for calls to more expensive models. The author does not deem Jev revolutionary, while noting that work on architecture, training, inference, calibration, and developer experience could make it a solid product.
Brief IA — L'actualité IA en français
L'essentiel de l'actualité de l'intelligence artificielle, décrypté et expliqué chaque jour.