JEV: Transforming an Open LLM into a Decision-Making Engine
Le brief IA que les pros lisent chaque soir
Les 7 actus IA du jour, décryptées en 5 min. Gratuit.
Inclus dès l'inscription : notre sélection des meilleurs guides & comparatifs IA.
Choisis ton rythme
Gratuit · Pas de spam · Désabonnement en 1 clic
Replacing the generation head of a language model with a classification head allows for instant and structured decisions. An open-source framework like Qwen2.5-Coder-1.5B-Instruct serves as a foundation to build this System 1 engine, designed to route and classify without resorting to verbose paragraphs.
Replacing the generation head with a classification head accelerates decision-making
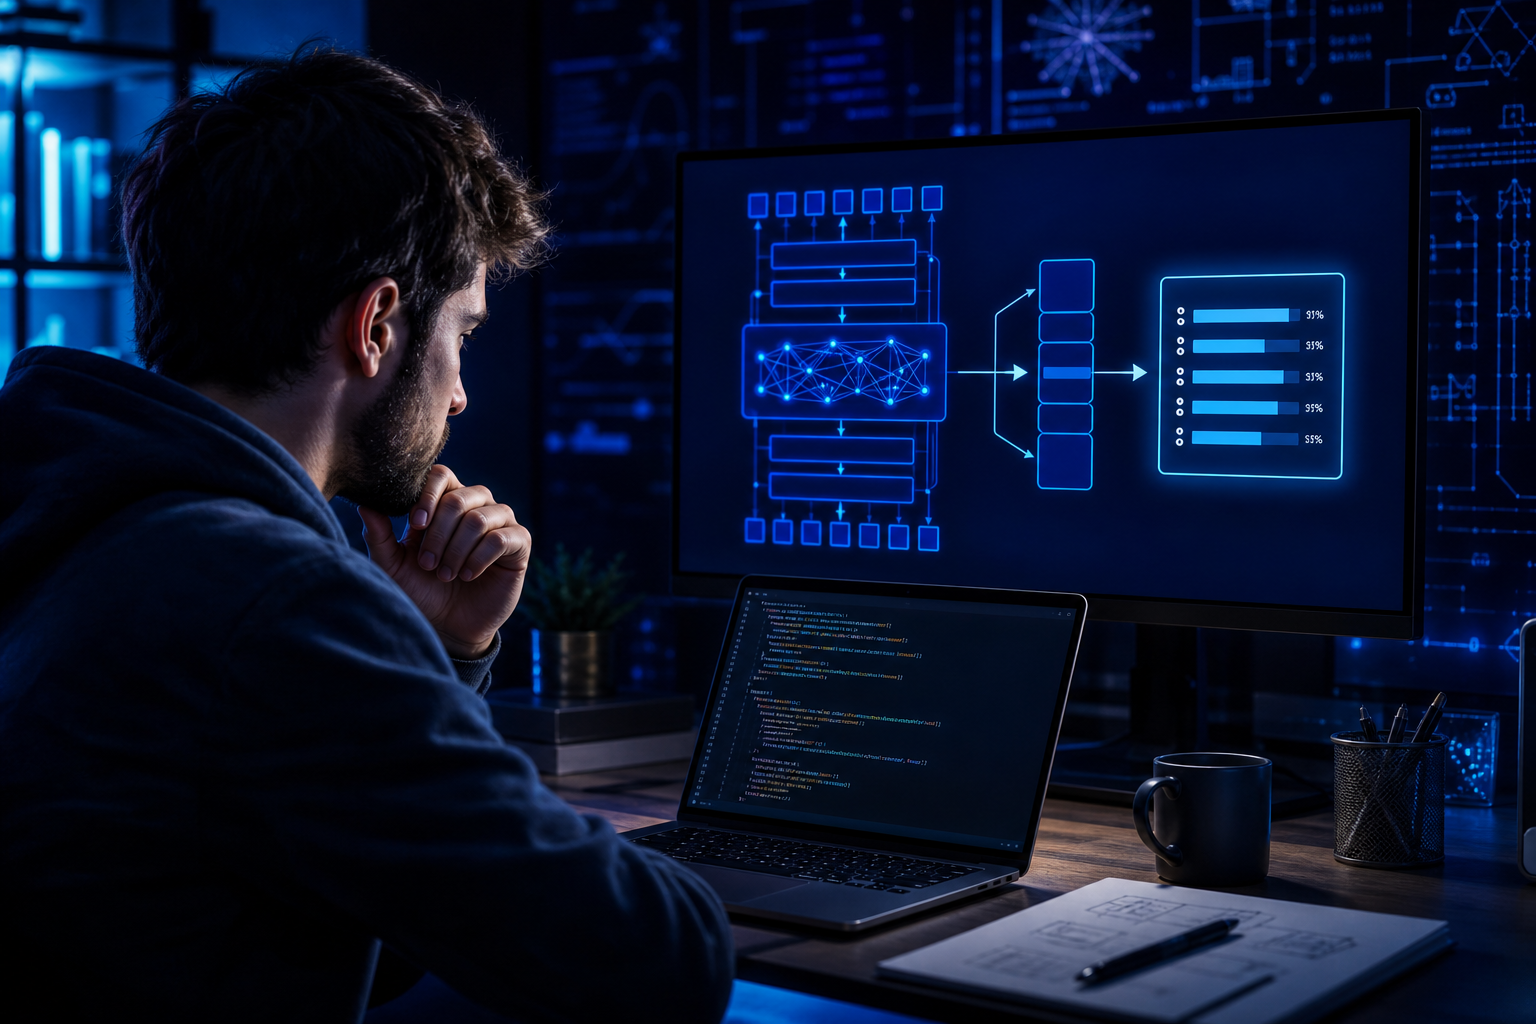
Transforming a language model into a decision engine involves replacing the generation head with a classification head. This change turns a slow loop operation into a single pass. The framework processes the context in one go, and then the classification head channels this understanding into a final decision, without generating words. The computer no longer traverses the network for each token; it executes once and delivers the decision in a fraction of a second. This shift from a word-guessing mechanism to a single-pass evaluator explains the speed and reliable switch-like nature of the system. In this architecture, the framework—which understands language, context, and nuances—remains unchanged. Only the head, interchangeable in modern architectures, changes its objective: instead of producing text, it outputs a mathematical score across predefined categories like True, False, or Spam.
Setting up a local JEV with Qwen2.5-Coder-1.5B-Instruct
The first step is to choose an open-source framework. The Qwen family is proposed as a candidate, with very compact variants suitable for a standard computer. For a fast and local decision engine, a compact version offers a balance between depth of understanding and performance. The example relies on Qwen2.5-Coder-1.5B-Instruct, a small model already fine-tuned for code. The presented project includes three scripts: model.py, train.py, and check_names.py, and can be installed with a simple pip command. Loading the model involves downloading the weights and using a tokenizer to convert text into readable units. The AutoModel API retains only the framework, even though the bundle also contains the word generation head. The first launch retrieves the files from Hugging Face; subsequent launches reuse the local copy. A code snippet illustrates the use of AutoTokenizer and AutoModel with the identifier Qwen/Qwen2.5-Coder-1.5B-Instruct. Once the framework is in place, the head swap described earlier must be applied to finalize the classification engine.
Routing messages in customer support with a deterministic switch
The practical interest is to build intelligent conditional instructions between the rigor of software rules and the understanding of LLMs. A typical use case is customer support. Upon receiving a message, before activating a slow and costly AI agent, it is essential to quickly identify whether it is an urgent incident, a billing question, or spam. A fast and deterministic switch routes the request to the appropriate processing without waiting for the drafting of an explanatory paragraph. Routing thus becomes reliable and swift, contributing to faster, cheaper, and less error-prone automated systems in the face of real-world data.
Why autoregressive generation limits speed
The transformers powering chatbots operate through autocompletion, predicting token by token until the stop word. This iterative loop is well-suited for creating long texts like poems or code, but it becomes a bottleneck when it comes to making a simple categorical decision, such as flagging spam. Even for such a label, the model assembles a complete sentence, with the unpredictability of phrasing that entails. In a software pipeline, one must then wait for this paragraph, read it, and extract the decision, leading to latencies, unpredictability, and risks of error if the phrasing varies. In contrast, a JEV engine examines the input in one pass and delivers a structured decision without intermediate text construction.
Cognitive foundations: from slow System 2 to fast System 1
The theoretical framework draws inspiration from the two systems of thought described by Daniel Kahneman. System 2, slow and reasoned, resembles the functioning of modern chatbots that develop a response step by step. System 1, fast and intuitive, serves as a model for the expected behavior of an instant decision engine. Until recently, developers relied on System 2-type models, even for trivial choices, due to a lack of robust alternatives. The contrast between a program that writes its response and another that decides in one step illuminates the ambition of a JEV engine: to bring rapid judgment to software, in the spirit of System 1. The book Thinking, Fast and Slow, published in 2011, popularizes this cognitive dichotomy.
If-then rules facing real-world cases
Traditional if-then rules are suitable for simple cases but fail on ambiguous or distorted inputs, such as a postcard, a padded envelope, or a crumpled letter, due to a lack of contextual understanding. Large language models have been mobilized for this type of messy information, thanks to their understanding of language and intentions, but their detailed textual responses are not ideal for quick binary decisions. A JEV engine focuses on structured decision-making, for example, a category accompanied by a confidence level, avoiding any verbiage. It retains the understanding of an LLM while eliminating the conversational aspect, which helps reduce response time.
Brief IA — L'actualité IA en français
L'essentiel de l'actualité de l'intelligence artificielle, décrypté et expliqué chaque jour.