LLM: A Decision Tree for Document Segmentation
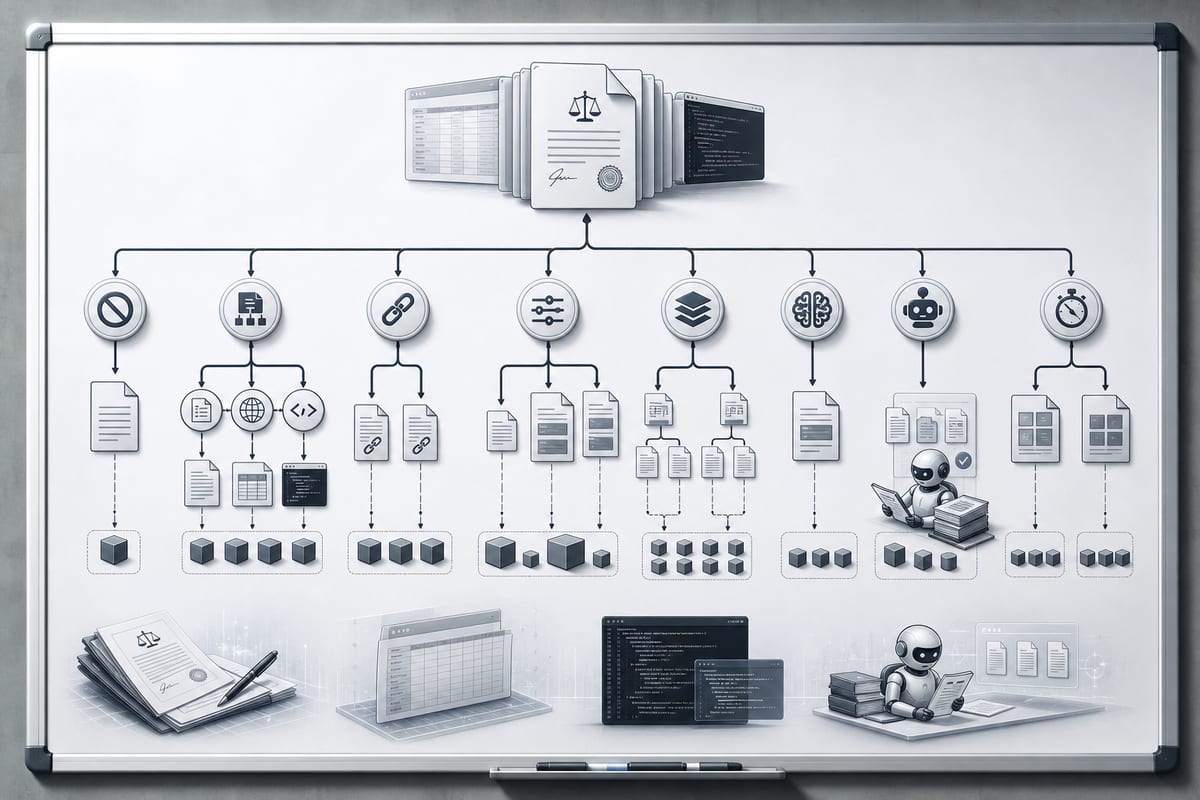
Choosing how to segment sources determines the quality of passage retrieval for LLMs. A six-step tree aims to avoid segmentation when unnecessary, rely on structure when it is reliable, and reserve costly methods for cases that justify them. The strategies align with the form of the corpus and the priorities of cost and latency.
Balancing Quality, Cost, and Latency in Segmentation
The decision tree explicitly raises the question of the trade-off between retrieval quality, cost, and latency. When quality is prioritized and the budget allows for a model call per document, it is recommended to opt for segmentation based on an LLM. If quality remains important but the cost of model calls per document is too high and topic changes cannot be anticipated, semantic segmentation based on the embedding distance of sentences should be used. When speed of execution and cost control are the main criteria, the tree leads to examining the following question and, as a last resort, resorting to fixed-size segmentation for rapid prototyping phases. The association table links each strategy to its usage context and cost, reserving LLM-based segmentation for complex documents with high stakes, while semantic segmentation is suitable for a moderate budget. The use of fixed segmentation is justified when speed matters more than the quality of the segments. The overall goal is to balance quality, computational cost, and implementation complexity.
Avoiding Segmentation When the Document Stands Alone and is Monothematic
The first step is to assess the necessity of segmenting the document. Short and independent contents, such as FAQ entries, product sheets, or isolated configuration excerpts, can generally be processed in a single embedding call and address a single topic. In this context, it is preferable to encode the document in its entirety without segmentation. If the text is too long or addresses multiple topics, the evaluation should continue down the tree.
Leveraging Structure When It Is Reliable
When the document has a clear internal structure, it serves as a guide. Markdown headers, HTML elements, PDF sections and tables, or code functions and classes provide relevant boundaries. If this structure is reliable and reflects logical units, document-based segmentation is indicated. Conversely, if the structure is inconsistent, incomplete, or not useful, other approaches should be considered in the next step.
Le brief IA que les pros lisent chaque soir
Les 7 actus IA du jour, décryptées en 5 min. Gratuit.
Inclus dès l'inscription : notre sélection des meilleurs guides & comparatifs IA.
Choisissez votre rythme
Gratuit · Pas de spam · Désabonnement en 1 clic
Preserving Dependencies at the Document Level
Some contents require that each segment retains the overall context. This is the case for a contract that defines a term in one section and reuses it later, or a technical specification whose terminology depends on a previous paragraph. In these cases, it is preferable to opt for late segmentation. This method involves first encoding the entire document using a model that accepts long contexts, then generating embeddings for each fragment separately. This way, each fragment retains the memory of the overall context, allowing for the handling of cross-references and long-distance dependencies.
Adapting Size and Levels of Granularity to Use Cases
Two distinct needs guide this step. If the information density varies within the same document, adaptive segmentation adjusts the size of the segments and the overlap according to the content, with smaller segments for dense passages and larger ones for lighter sections. If the same corpus needs to answer broad questions and very specific inquiries, hierarchical segmentation is necessary, with coarse parent segments and fine child segments. These approaches target respectively uneven density corpora and those requiring answers at multiple granularities.
Choosing Based on the Heterogeneity or Uniformity of the Corpus
The nature of the collection guides the final choice. For a heterogeneous collection, agentic segmentation delegates to an agent the inspection of each document and the selection of the appropriate strategy. Conversely, a reasonably uniform corpus lends itself well to recursive segmentation, which first segments at paragraph boundaries, then at sentence boundaries, and finally at word boundaries, until the target size is reached, while preserving a natural structure without specific analysis per document.
Assumptions, Compatibilities, and Effects of Poor Choices
Each strategy relies on a specific assumption: fixed size with overlap compensation, recursive based on paragraph and sentence boundaries, document-based aligned with semantic structure, semantic via embedding distances, late for segments dependent on the whole, adaptive for variable density, LLM-based to detect breaks missed by other signals, and agentic when no single rule suffices. Used in the right context, these methods justify their complexity; misaligned, they add overhead without retrieval gain. For instance, semantic segmentation is unnecessary on a short FAQ, while fixed-size segmentation may split related clauses in a contract. These incompatibilities lead to retrieval issues stemming from preprocessing, not generation. Therefore, the choice must consider the structure, complexity, and data retrieval needs.
Brief IA — L'actualité IA en français
L'essentiel de l'actualité de l'intelligence artificielle, décrypté et expliqué chaque jour.