LLM Judge: Three Biases and Countermeasures, 80% Human Agreement
Le brief IA que les pros lisent chaque soir
Les 7 actus IA du jour, décryptées en 5 min. Gratuit.
Inclus dès l'inscription : notre sélection des meilleurs guides & comparatifs IA.
Choisis ton rythme
Gratuit · Pas de spam · Désabonnement en 1 clic
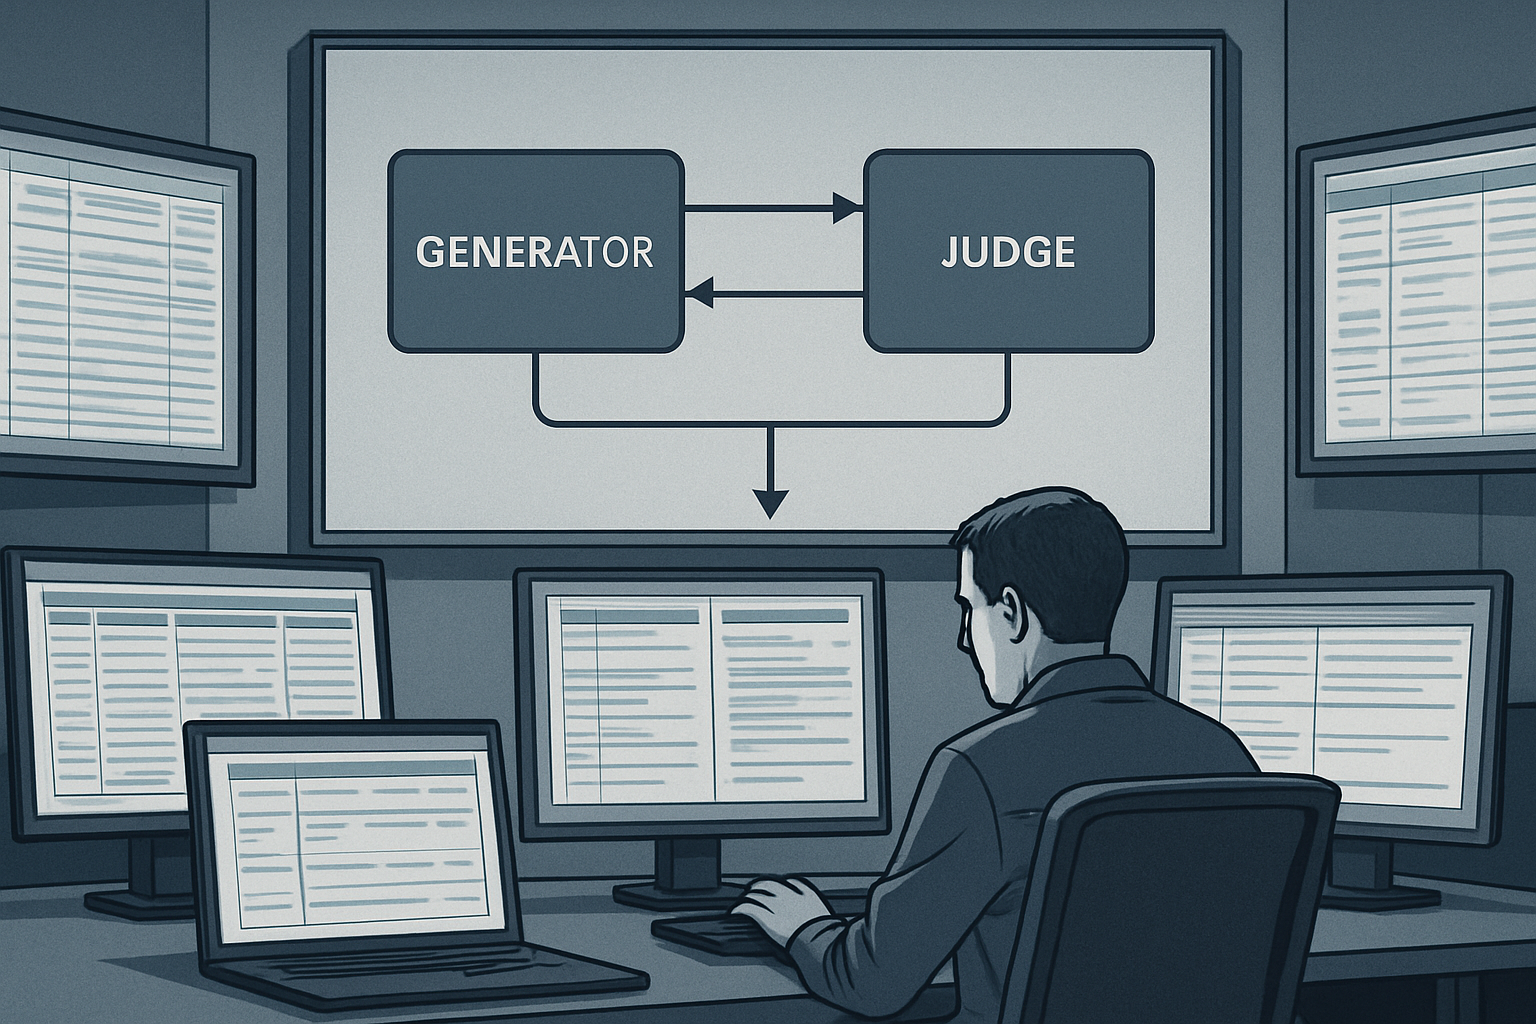
A judge LLM can overestimate written responses in the style of its own model family. Separating the roles of generator and evaluator, rewriting the scoring rubric, and regular calibration against human judgments reduce these discrepancies. Plausible yet subtly incorrect cases are now systematically referred to a human examiner, regardless of the confidence displayed by the model.
Ambiguous queries automatically routed to a human
The focus is on detecting cases that require automatic human judgment, regardless of the judge's scores. Plausible yet subtly incorrect queries, which were the source of the initial incident, have consistently shown the lowest agreement between the judge model and the human examiner. They are now flagged by default for human review, irrespective of the confidence reported by the system, as this confidence has proven unreliable for this category.
Three biases that distort an LLM's judgment
Several recurring biases influence an LLM tasked with judging responses. The personal preference bias leads a model to rate its own outputs or those from its family more favorably, a mechanism tied to its familiarity with low-perplexity texts, often produced by similar models. The verbosity bias means that between two correct responses, the longer one often prevails, especially if the scoring rubric values completeness. Finally, the position bias makes the decision sensitive to the order of response presentation, to the extent that a simple inversion can change the verdict. These biases do not preclude the use of an LLM as a judge, but its scores should not be treated as objective measures. They represent the opinion of a consistent yet biased evaluator, whose blind spots must be understood before weighing its judgments.
The incident reveals a preference for its own model lineage
The error was not isolated: after resubmitting the same query and prompt in isolation, the judge reapproved a query with the same missing filter and the same confidence. The pattern was made explicit by comparing a batch of decisions against the opinion of a human examiner. The generator and judge shared the same model, not by design but due to cost standardization. By substituting queries produced by another model of comparable quality, the judge became significantly stricter and identified flaws it accepted in its own outputs. The query that triggered the incident passed review not because the judge was misaligned, but because the review step, assumed to be neutral, structurally favored its own productions.
Separate model families and rewrite the rubric
The first effective countermeasure was to assign judgment to a model from a different family than that of the generator, making it a neutral third party and directly addressing the personal preference bias. For example, the judge can be selected as "gemini-2-5-pro" if the generator contains "gpt," otherwise "gpt-4o." This change does not affect verbosity, as this bias primarily depends on the scoring rubric. The rubric has therefore been modified to penalize unnecessary length and reward a shorter correct response, including a concrete example in the prompt where a brief and correct query outperforms a longer version. Such an example proved more influential than general guidelines.
Regularly measure agreement with human evaluators
The robustness of a judge LLM must be calibrated on a reserved sample and continuously verified. A set of queries already scored by the judge was extracted and then rated by an examiner familiar with the pattern, without access to the model's verdicts. The agreement between the two was then measured and established at around 80%, a magnitude typical for this pipeline at the time of testing, which should not be considered a reference for other tasks or rubrics.
A rapid sorting tool and test set creation
When used with safeguards, a judge LLM provides a quick first-pass decision and facilitates the bootstrapping of labeled datasets: evaluating a raw batch, having a human resolve disagreements, and building the evaluation set based on this loop rather than labeling everything by hand. The identified biases necessitate treating its verdicts as a first opinion that calls for a second at a defined pace, without abandoning this approach.
Brief IA — L'actualité IA en français
L'essentiel de l'actualité de l'intelligence artificielle, décrypté et expliqué chaque jour.