LLM Novelty Judges: Unstable Verdicts, High Costs
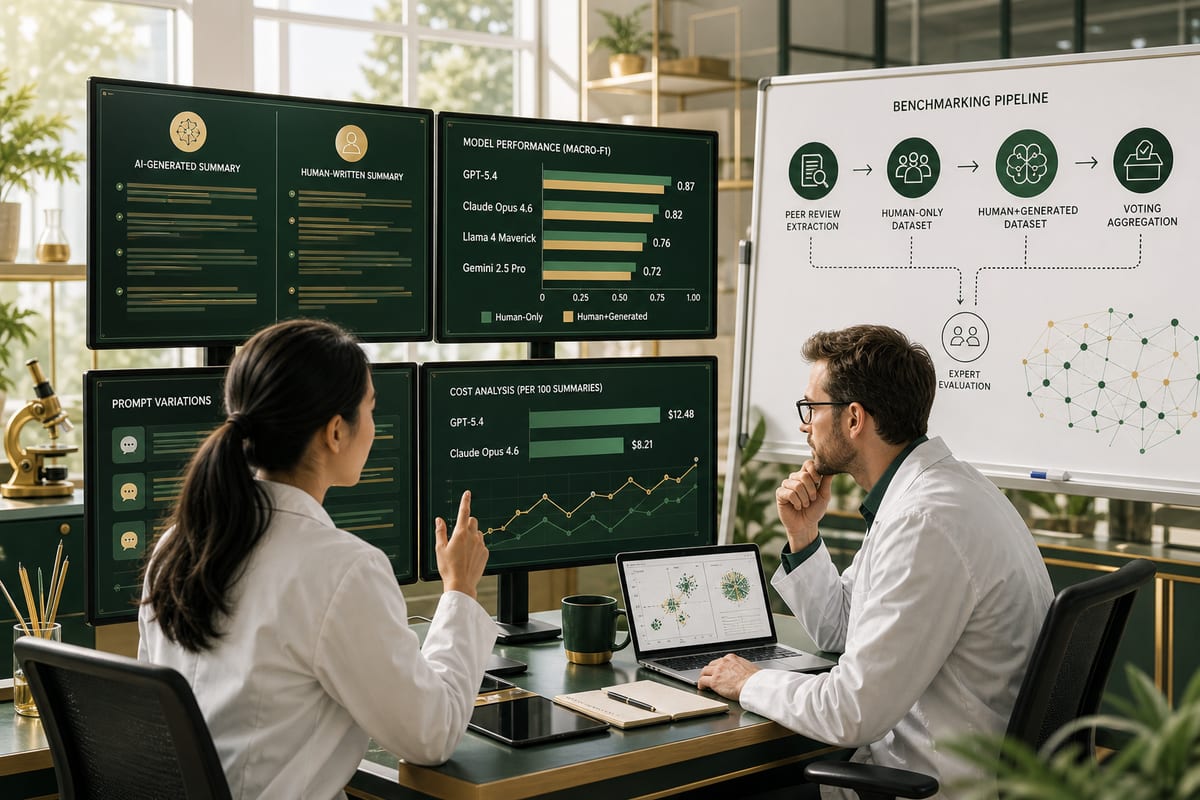
A public benchmark compares six models on the evaluation of the novelty of scientific ideas. Minor modifications to prompts can reverse verdicts and significantly reduce accuracy, especially when dealing with ideas generated by AI. Specialized, much more expensive pipelines lag behind a simple reference. Data and comprehensive tools are provided to reproduce and extend these tests.
Major Performance Gaps Despite High Costs
Across the Human+Generated set, a reference configuration using Claude Opus 4.6, with low reasoning and a majority vote on three calls, achieves a macro-F1 score of 0.854 for $2.59. Idea Novelty Checker, based on literature retrieval and reevaluation, scores 0.642 for $30.66, while Sakana AI's AI Scientist, supported by iterative research in Semantic Scholar, reaches 0.772 for $82.05. Both dedicated evaluators used Claude Opus 4.6 with a single call per decision. The simple reference is both more accurate and significantly less expensive than these specialized systems. Furthermore, an agentic judge, GPT-5.6 Sol, equipped with a very high reasoning budget and live search limited to arXiv, achieves a macro-F1 score of 0.78, compared to 0.89 for Claude Opus 4.6 in the same comparison, while costing about ten times more per decision at current API rates.
A Few Words in a Prompt Are Enough to Reverse Verdicts
The way the question is posed to the model accounts for most of the observed variations. With GPT-5.4, stating that only one idea per pair is truly novel leads to 93.5% accuracy on Human+Generated. Removing this constraint and simply asking which is novel drops the accuracy to 40.9% on the same pairs, with verdict reversals in more than half of the cases. Drops of over 50 percentage points have been observed depending on the wording. No prompt stands out as superior in all circumstances: even removing an instruction aimed at excluding trivial or incremental contributions improves some judges while degrading others.
Human Ideas vs. Generated Ideas: Contrasting Stability
For ideas written by humans and accompanied by strong originality cues, switching from one prompt to another shifts accuracy by about seven percentage points on average. Specifically, Claude Opus 4.6 varies by 21 points on this same set. Judges appear relatively stable on human texts, while being much more sensitive to variations in instructions on generated ideas. In comparisons between generators, such as Claude Opus 4.5 versus Claude Sonnet 4.5 or GPT-5.4 versus GPT-5.1, one-quarter to one-third of the verdicts change depending on the prompt, on average across six judges.
Le brief IA que les pros lisent chaque soir
Les 7 actus IA du jour, décryptées en 5 min. Gratuit.
Inclus dès l'inscription : notre sélection des meilleurs guides & comparatifs IA.
Choisissez votre rythme
Gratuit · Pas de spam · Désabonnement en 1 clic
How the Human-Only and Human+Generated Test Sets Were Constructed
The evaluation pipeline relies on the ICLR 2026 evaluations, extracting passages where reviewers explicitly discuss originality. Acceptance did not serve as a substitute for novelty. The high-novelty set includes 154 ideas from articles in the top 10% of their field, for which novelty was positively identified and never contested by reviewers. The low-novelty set gathers 145 ideas from rejected articles in the bottom 10%, where doubts about originality were raised without positive validation. A separate verification confirmed the polarity of the novelty signal in 47 out of 50 cases, with disagreements not altering the interpretation. These two sets form the Human-Only dataset. The Human+Generated framework pairs the same 154 validated ideas with 154 ideas proposed by a basic LLM generator, without literature search, tools, iteration, or feedback, under the assumption of weak labels suggesting these ideas are less novel. An expert reviewed 30 selected pairs towards the difficult cases, consistently preferring the human idea and not judging any of the generated ideas as novel. Both human and generated statements were also rewritten in a common format to eliminate any writing style effect.
Testing Protocol: Pointwise and Pairwise Comparisons, Controlled Factors
Six LLM judges were evaluated in pointwise and pairwise comparisons. The protocol varied one factor at a time: prompt, reasoning budget, access to related articles, formatting of ideas, decision aggregation, and generator model for AI ideas. Seemingly minor changes in these parameters produced divergent judgments on the same content. Neither document retrieval nor the allocation of additional reasoning systematically resulted in better verdicts. Two dedicated novelty evaluators underperformed a simple reference, despite higher costs. All judges in the agentic comparison were executed once per idea on Human+Generated.
Open Tools to Investigate an Unresolved Issue
The Old Ideas, Novel Problems project comes with a benchmark, data, code, and an automated pipeline, allowing the community to replicate and extend the evaluation of novelty judges. The authors indicate that LLM evaluation of novelty remains unstable, particularly for generated ideas, and that overall reliability remains an open issue. This challenge is central for ideation systems that must produce truly original axes and for judges, often LLMs themselves, tasked with arbitrating the distance to prior works. In the absence of a construction standard and given the decisive influence of configuration choices, validation on human ideas alone is insufficient. The proposed tools aim to document these effects and improve the robustness of evaluation practices.
Brief IA — L'actualité IA en français
L'essentiel de l'actualité de l'intelligence artificielle, décrypté et expliqué chaque jour.