Microsoft: 2.5 Million Spam Messages Detected via Unicode Bypass
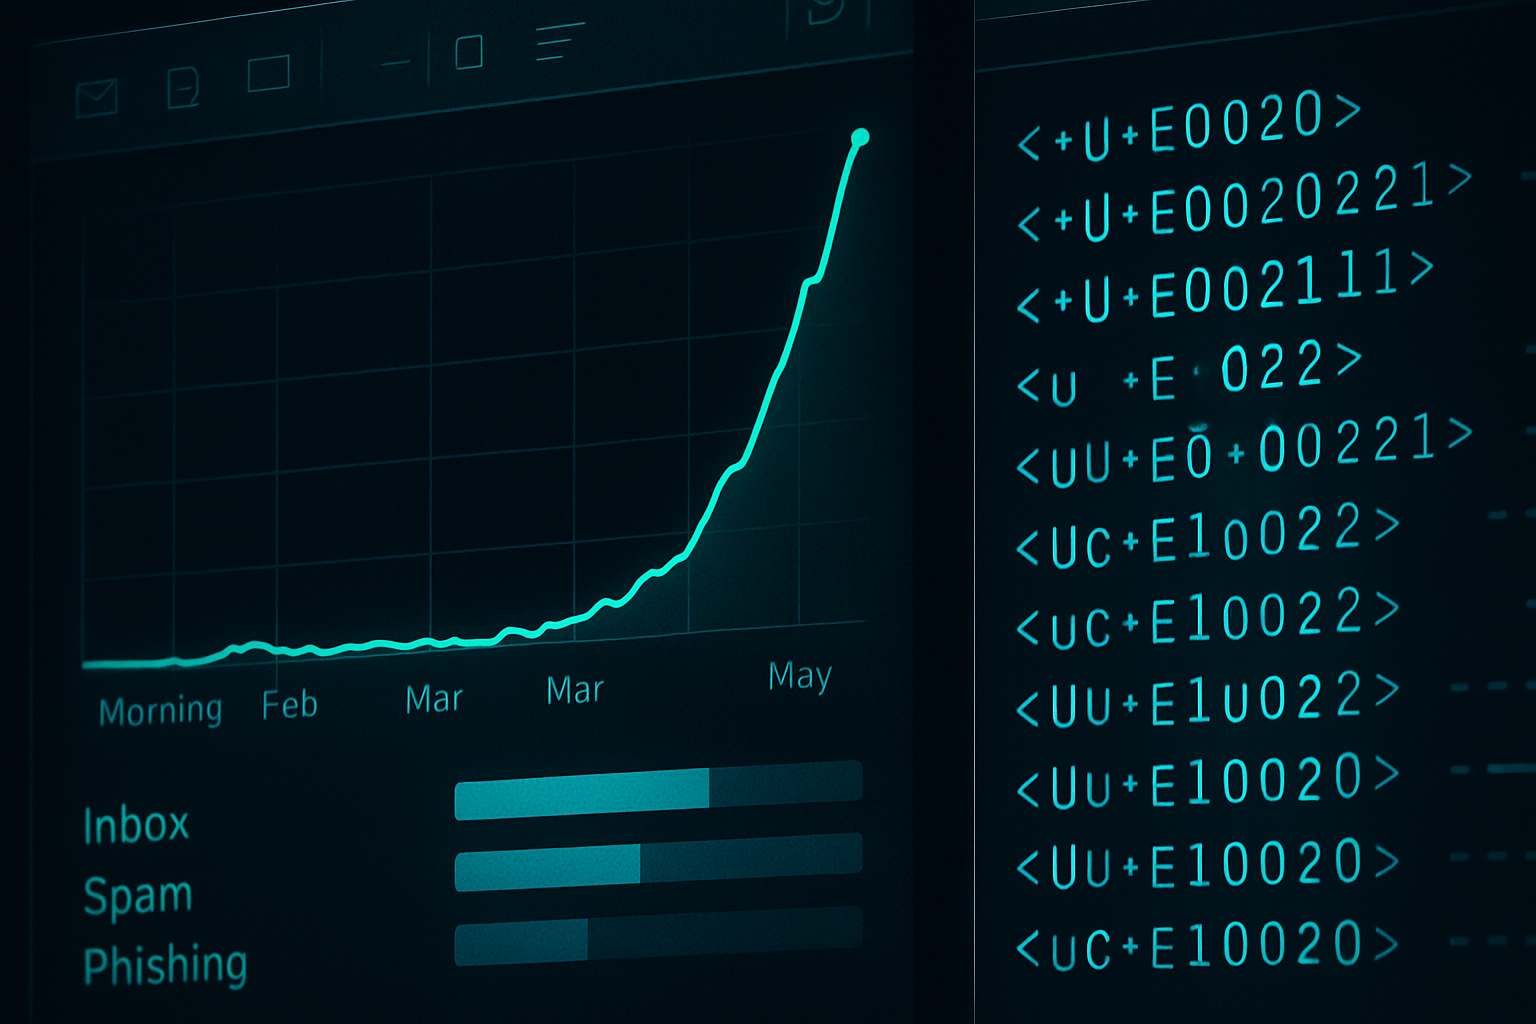
Invisible Unicode tags are now being used to disguise keywords in mass campaigns. Microsoft reports a sharp increase in detections starting in early February, followed by a decline in mid-May. This trick, which originated from prompt injection attacks against LLMs, disrupts email classifiers based on ML and NLP.
Detections: from 21,000 per day to 2.5 million in four days
This year, Microsoft observed a significant rise in spam messages exploiting invisible characters. Starting from a day in early February, Microsoft Defender for Office went from approximately 21,000 detected ASCII bypass signatures per day to over 1.3 million. In just four days, detections peaked at 2.5 million. This volume remained high for months before sharply declining in mid-May.
Why filters stumble over invisible characters
According to Microsoft, invisible characters to the user but present at the text processing level are enough to obscure keywords before evaluation by a detector. The challenge for attackers is to disrupt the ML and NLP models that increasingly handle spam and phishing classification. Unless the message is converted into an image and OCR is applied, a filtering system may miss these manipulations. A standard email classifier often segments text into tokens or sub-words, and the insertion of a character like U+E0020 can prevent the recognition of a familiar unit. The text can then be split into unexpected fragments, produce rare sub-tokens, or, if normalization removes the character, revert to the original word.
Le brief IA que les pros lisent chaque soir
Les 7 actus IA du jour, décryptées en 5 min. Gratuit.
Inclus dès l'inscription : notre sélection des meilleurs guides & comparatifs IA.
Choisissez votre rythme
Gratuit · Pas de spam · Désabonnement en 1 clic
A trick from attacks against LLMs
ASCII bypass, known for camouflaging prompt injection instructions, emerged two years ago as a way to make them more stealthy. The method relies on special Unicode tags, such as U+E0041 for "A" and U+E0061 for "a," belonging to a block of 128 tags that mimic part of ASCII while remaining nearly invisible to humans. Formulated this way, instructions can be read by an LLM without appearing to a human reader.
Targeting trigger words, between old tricks and new methods
Spam actors seek to outsmart filters that scrutinize amounts and terms like "credit" or "term." By sprinkling invisible text within a word like "financing," a filter may only see segments like "fun" and "ding," while the recipient reads the complete word. The camouflage of trigger words is not new: zero-width spaces and non-breaking spaces have been used for decades to thwart literal searches and disrupt patterns targeted by regex filters.
Filters caught off guard and mitigation strategies
The adoption of hidden Unicode tags is likely explained by the lag of certain filters that did not yet detect them, and by the desire to counter the gains brought by ML and NLP in spam detection. A post published on Thursday provides advice to developers on how to adapt filters to account for this ASCII bypass.
Brief IA — L'actualité IA en français
L'essentiel de l'actualité de l'intelligence artificielle, décrypté et expliqué chaque jour.