Microsoft: Clearing Context Boosts AI Agents by 66%
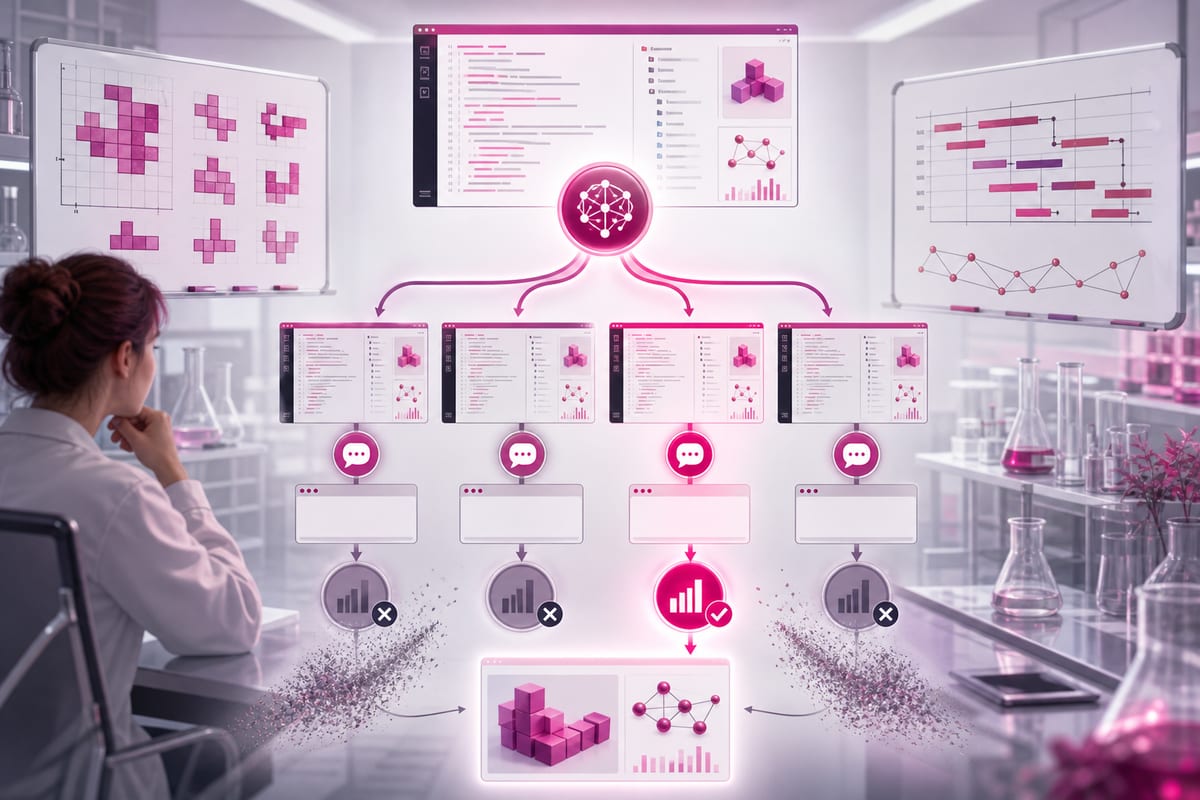
Researchers at Microsoft report that AI agents get stuck in "idea pools" as conversations lengthen. By splitting the process into branches and starting anew with a blank context, Fork-and-Flush improves the average score and consistency without additional computation. The discrepancies between executions remain pronounced at the edge of the models' capabilities, making resets relevant even with more powerful systems.
With the same budget, an average score raised to 0.78 and reduced variance
In comparable trials, Fork-and-Flush achieves a normalized average score of 0.78. Single executions peak at 0.47, and the best of 4 reaches 0.54. The reported relative gains are 66.0 percent compared to single executions and 44.4 percent compared to the best of 4. The method also achieves the highest average score on 12 of the 13 evaluated tasks. Performance dispersion decreases, with a normalized standard deviation of 0.16 compared to 0.26 for single executions. Simply clearing the context without creating branches already improves results by 22 percent. Individual executions cover durations ranging from several hours to over 100 hours.
Fork-and-Flush resets the dialogue but retains the produced work
The method combines two phases. First, forking divides the agent into K parallel branches, each inheriting the existing workspace and files. Then, flushing clears the entire conversation context for each branch while retaining the workspace, allowing a new conversation to resume based on the code and results already generated. The process launches branches with fresh contexts, keeps only the best one, and discards the others. The conversation history disappears, but the work artifacts remain. A renewed context restores diversity in exploration, while a branch that retains the parent context tends to return to the same idea pool. Branches with fresh contexts can move to other pools and achieve better scores.
Le brief IA que les pros lisent chaque soir
Les 7 actus IA du jour, décryptées en 5 min. Gratuit.
Inclus dès l'inscription : notre sélection des meilleurs guides & comparatifs IA.
Choisis ton rythme
Gratuit · Pas de spam · Désabonnement en 1 clic
Why agents stagnate despite increased computation
The self-searching agents examined operate by proposing, evaluating, and refining solutions iteratively, but they can encounter stagnation even when computational resources are increased. Eight independent launches of an identical agent applied to the same task generated final scores ranging from 68.3 to 100.0, variations that persist despite additional computational input. The two-dimensional representation of solutions highlights that each launch remains confined to a restricted area, corresponding to an idea pool, where it continues to explore the same directions. Agents then invest most of the remaining budget in a low-yield region instead of exploring other approaches. This behavior persists even when they periodically compress their conversation history. A single execution illustrates this trend by remaining in the same pool.
Tests on 13 tasks and Qwen3.5 models show a peak in variance at the limits of capabilities
The evaluations cover 13 long-duration tasks, including polyomino packing, job-shop scheduling, cryptanalysis, CIFAR classifier compression, and VLIW kernel optimization, with agents executed via the GitHub Copilot CLI relying on GPT-5.6-terra and GPT-5.5. To assess the effect of model size, MAX-3-SAT problems were used with Qwen3.5-4B, 9B, and 27B. The gap between different executions takes the form of an inverted U-shaped curve, peaking for tasks close to the limits of capabilities, situated midway between a random response and that of a benchmark solver. The models almost consistently manage to solve the simplest tasks, fail on the most challenging ones, and display variable performance at the boundary, regardless of the model size used. Open research problems lie precisely at the boundary between what models can do and what they cannot, and exploitable variability should remain present as models advance, with this boundary shifting towards more complex cases. These observations suggest that regular context resets would still be beneficial even for cutting-edge agents.
Brief IA — L'actualité IA en français
L'essentiel de l'actualité de l'intelligence artificielle, décrypté et expliqué chaque jour.