Suno Launches Speech, AI Voice, and Music in Public Beta
Le brief IA que les pros lisent chaque soir
Les 7 actus IA du jour, décryptées en 5 min. Gratuit.
Inclus dès l'inscription : notre sélection des meilleurs guides & comparatifs IA.
Choisis ton rythme
Gratuit · Pas de spam · Désabonnement en 1 clic
Suno expands its platform to spoken text with Speech, capable of combining voice and music into a single track. The public beta, available on both web and mobile, comes with two creation modes and a maximum duration of about eight minutes, while the editor acknowledges imperfections and promises improvements.
Announced limitations for the beta and a duration of about eight minutes
Suno indicates that Speech is still imperfect and will continue to refine it based on user feedback. Jack Brody summarizes the state of the product by reminding us that "beta really means beta." He cites current behaviors, such as British accents that may drift to Australian and then back, or overly dramatic pauses. He also anticipates that unexpected uses will emerge. Additionally, the generation is limited to a maximum duration of about eight minutes.
Solo voice or mixed track, and two creation modes
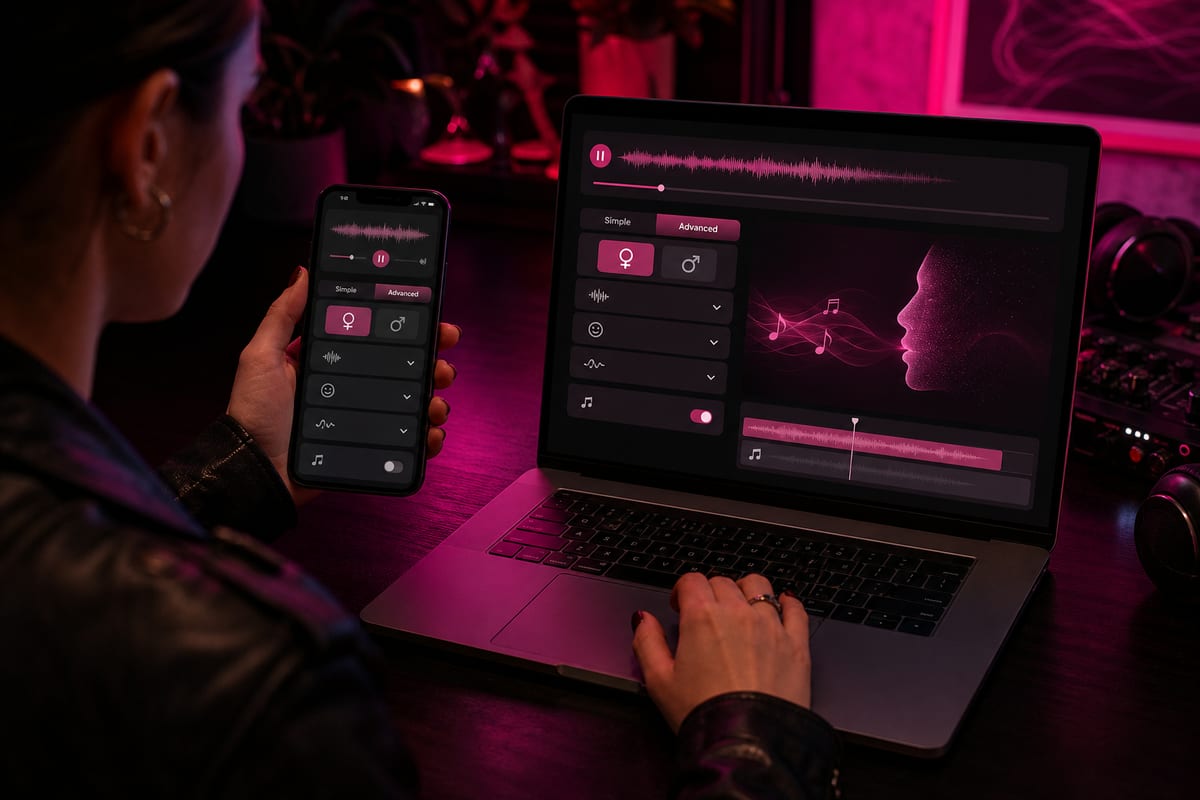
Speech can produce a single track combining voiceover and background music, but the musical accompaniment remains optional and can be disabled to keep only a clear voice. Two modes are available: Simple, which uses only a descriptive prompt — such as "a pirate captain rallying his crew" — and Advanced, which supports a custom script. The Advanced mode also offers the ability to modify the vocal genre, speaking style, and diversity of each output. To access this feature, users must go to the Create tab and select the Speech option.
Beta availability and positioning against voice industry players
Speech is available in public beta on Suno's web and mobile platforms. The company thus adds a spoken voice generator to its offering, with Jack Brody reminding that music remains central to Suno, while expanding the platform to other forms of expression. He presents Speech as an audio model capable of producing voice and music together in a coherent track. The launch comes at a time when DeepMind has been exploring voice synthesis for a decade, Adobe offers a dedicated tool, and ElevenLabs has established itself since 2023. Furthermore, Suno's music generator has been the subject of numerous legal challenges. Suno mentions potential uses such as a calming ambiance for poems or a more energetic tone for dramatic voiceovers and encouraging speeches.
Brief IA — L'actualité IA en français
L'essentiel de l'actualité de l'intelligence artificielle, décrypté et expliqué chaque jour.