TRELLIS.2: LoRA Scripts to Adapt Your 3D Models
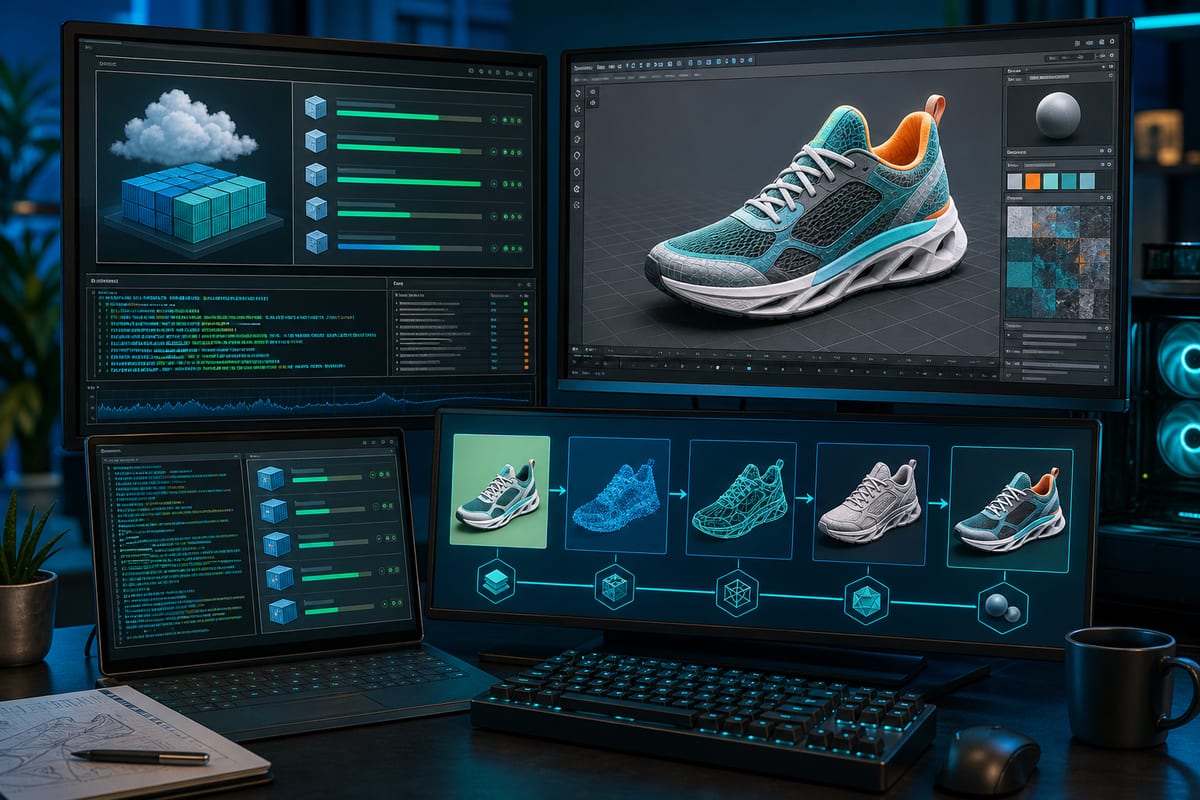
Scripts and published containers allow for fine-tuning TRELLIS.2 with LoRA, either locally or via Hugging Face Jobs. The method targets structure and geometry, with concrete figures at stake: 16 views per object and approximately one hour for 188 meshes on a100-large. Datasets can be pushed and reused on the Hub.
A measured flow: 16 views per object and one hour for 188 models
Preprocessing generates 16 views of each object using Blender, which then serve as conditioning images for LoRA training. On an a100-large job, preparing a batch of 188 objects took about an hour. The hardware is specified with the argument --flavor a100-large, corresponding to an 80 GB card. Parameters include a timeout of 6 hours, options --holdout 0.05, --views 16, and --workers 8, and publishing outputs to a Hub repository. In detached mode, the tool displays the job ID and URL, and logs are accessible via a dedicated command.
What’s delivered: two Docker images and a four-step path
Ready-to-use scripts and containers allow for fine-tuning TRELLIS.2 locally or on Hugging Face Jobs. Two Docker images are provided: one for preprocessing and the other for fine-tuning. The recommended workflow consists of four actions: granting data access to the containers, setting task parameters, running the preprocessing image, and then the training image. The preprocessed dataset is saved for reuse in future sessions.
Targeting shape: LoRA on two DiTs and not on texture
LoRA adapters are applied only to the sparse structure DiT flow and the shape DiT flow, which determine the shape and geometry of the object. The texture DiT flow is frozen to preserve its current capabilities. The dataset used includes diffuse color maps but no separate material maps, with the former mixing surface color and lighting; thus, they do not constitute correct targets for training texture. Inappropriate training could lead the model to confuse lighting with material and cause catastrophic forgetting. On a subset of 188 shoes, initial tests showed incorrect soles with the pre-trained model; a LoRA is being experimented with to improve this aspect, while the colors and textures of the base model are deemed satisfactory.
LoRA configuration: approximately 9.3 million parameters in total
The presented configuration results in a total of about 9.3 million adapter parameters for the two relevant DiTs. Rank 8 modules are placed in the attention and MLP layers of the structure DiT, while rank 16 modules are used in the attention layers of the shape DiT. The rank determines the size of the adapter matrices, and a higher rank increases their learning capacity. With 188 shoes from 1,030 GSO objects, LoRA is favored over full fine-tuning, which is considered much more costly and likely to overwrite useful model knowledge.
Le brief IA que les pros lisent chaque soir
Les 7 actus IA du jour, décryptées en 5 min. Gratuit.
Inclus dès l'inscription : notre sélection des meilleurs guides & comparatifs IA.
Choisissez votre rythme
Gratuit · Pas de spam · Désabonnement en 1 clic
Under the hood: five steps, O-Voxel, and sparse transformers
The TRELLIS.2 pipeline follows five steps: background removal via BiRefNet, encoding the image into tokens using DINOv3-L, predicting a coarse structure, generating detailed geometry, and then defining materials before exporting a textured mesh. The structure flow generates a latent 16³ × 8, decoded into a 64 × 64 × 64 occupancy grid; LoRAs are added to influence geometry. The O-Voxel representation retains only surface voxels and stores local geometry and material attributes; a CPU converts a mesh into O-Voxel in a few seconds, and the reverse operation is performed in seconds on a GPU. Inherited from TRELLIS, the sparse structured latents use only about 10% of the voxels, and the shape and texture flows rely on sparse transformers, while the structure flow is dense. The O-Voxel geometry is produced at a resolution of 512 × 512 × 512; LoRAs are also added to the shape DiT. Materials are then defined and decoded into base color, metallic, roughness, and alpha maps, without LoRA at this stage, before exporting a GLB. TRELLIS.2 continues the lineage of TRELLIS, which introduced a unified latent representation converted by decoders, avoiding format-specific models. The stated goal is to improve performance on a specific category of objects by fine-tuning only the relevant components.
The scripts run on local GPU or via Hugging Face Jobs
The workloads run on Hugging Face Jobs, used for preprocessing and training, or via Docker on a local GPU. An HF_TOKEN is required, and access to the restricted DINOv3 model must be granted to the account. Personal datasets must be pushed to the Hub before starting. Two Docker images include dependencies to avoid lengthy installations, respectively for preprocessing and fine-tuning. On Jobs, the token is passed as an encrypted variable without being written in the image; the URI cr.hf.co/...:latest designates the image, followed by the executed command. Other arguments are supported, including for local execution. The typical process consists of three parts: converting GLB or OBJ meshes and rendering input images, launching training by DiT with LoRA configuration, and then relying on containerized code to load data, insert adapters, and train models.
Brief IA — L'actualité IA en français
L'essentiel de l'actualité de l'intelligence artificielle, décrypté et expliqué chaque jour.