ML Engineers, AI or LLM: What the Titles Really Mean
Le brief IA que les pros lisent chaque soir
Les 7 actus IA du jour, décryptées en 5 min. Gratuit.
Inclus dès l'inscription : notre sélection des meilleurs guides & comparatifs IA.
Choisis ton rythme
Gratuit · Pas de spam · Désabonnement en 1 clic
Job titles in AI are multiplying and colliding, but the responsibilities do not always follow suit. Three roles stand out based on what they actually deliver. To navigate and prepare, it’s better to read the list of tasks than the title, and to focus on a common technical foundation.
Companies Change Titles Without Modifying Evaluation Criteria
AI job titles remain inconsistent and are likely to stay that way for some time. Companies are renaming roles faster than they update their evaluation criteria, which limits the relevance of the title. To apply effectively, one must focus on the concrete elements of a job posting. Two questions are crucial: what will be built in the first 90 days and what will be owned afterward. These provide more information than the title. Before committing, it is advisable to refer to the list of tasks to be built, owned, and maintained in a year. This is the most accurate description, regardless of the job title.
What a ML Engineer Does: From Model to Data in Production
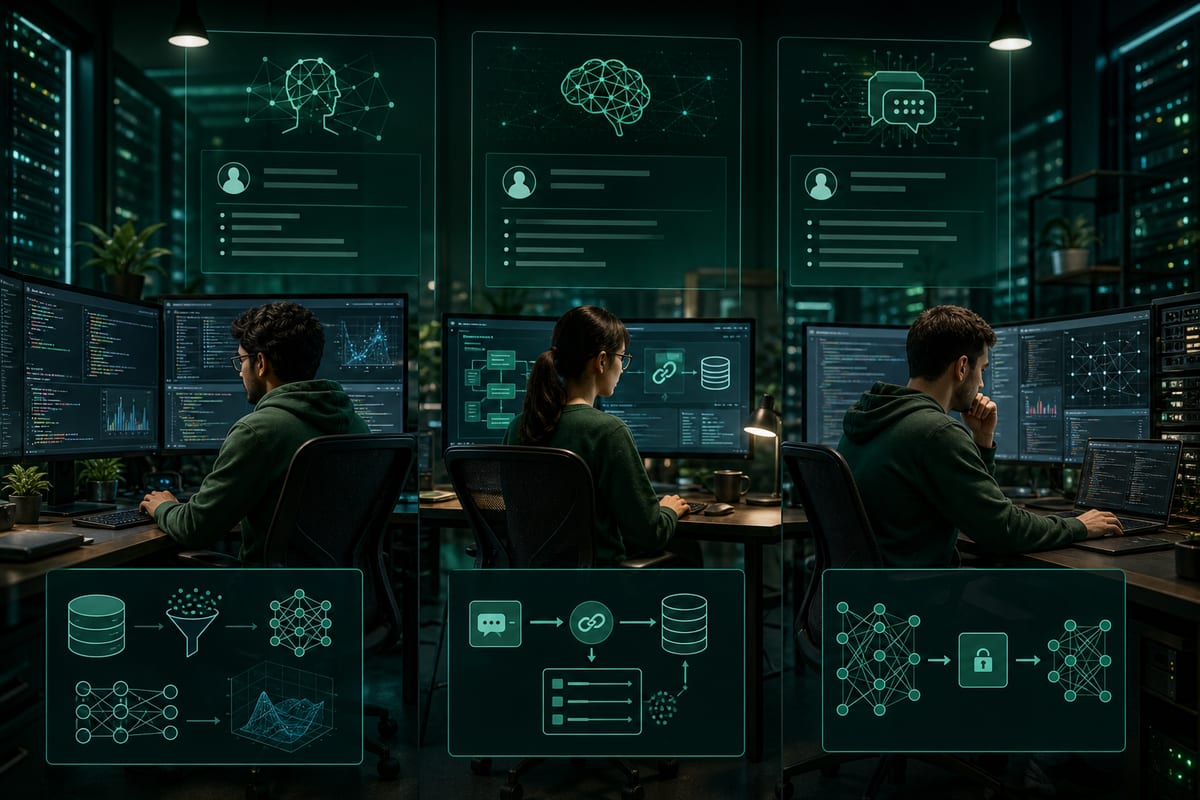
A machine learning engineer trains and delivers a model from data. After a prototype validated by a data scientist, they transform the approach into a reliable production system capable of processing new data. Their work loop covers data collection and cleaning, algorithm selection, training, validation via RMSE or confusion matrix, deployment, and then monitoring and retraining. Tools include Python, PyTorch or TensorFlow, scikit-learn, and feature stores like Amazon SageMaker or Databricks. Deliverables are concrete: recommendations, fraud detection, demand forecasting, or fraud scores per transaction. Most of the time is focused on data; quality issues, label leakage, or poorly designed feature windows affect a model long before the algorithm choice.
What an AI Engineer Does: Connecting LLMs to Products
The AI engineer starts with an existing model, often a large model exposed via API, to integrate it into a product: support tool, internal search, or multi-step agent. Their day is divided between prompt design, retrieving and connecting to the model, evaluating and monitoring for hallucinations or quality drops, as well as backend work on APIs and databases, along with prototyping and writing for other teams. Typical tools include Python or TypeScript, orchestrators like LangChain, LangGraph, or LlamaIndex, and vector databases such as Pinecone or Qdrant. Training from scratch is not on the agenda. A common misconception is that candidates think they will train models, while they mostly spend time on pipelines and prompts. The work begins after the model has been trained and validated and ends when the system reliably serves real users.
What an LLM Engineer Does: Same Scope, Plus Fine-Tuning
The LLM engineer covers most of the tasks of the AI engineer, with the added responsibility of fine-tuning language models. Using techniques like LoRA or QLoRA, they adjust the weights of a pre-trained model on domain-specific data when a general model is insufficient for a narrow task. Experienced practitioners first seek to avoid fine-tuning: a better-designed retrieval, a longer prompt, or another base model often solve the problem at lower cost and without ongoing maintenance. Fine-tuning comes into play after alternatives have been ruled out.
Heterogeneous Job Listings and Salaries: The Title Doesn’t Tell Everything
In job postings, the same field is hidden behind varied titles like AI Engineer, Applied AI Engineer, or LLM Engineer, with often similar responsibilities: Python, language model API, retrieval, production. The specifics diverge: experience with LangChain, LoRA fine-tuning, API calls, and clean evaluation code. The same title can cover different jobs, and career decisions often align too closely with the title. Candidates expect to train models full-time and discover other realities. Examining job postings and conversations with candidates shows that the useful boundary is what one builds, owns, and maintains six months later. Historically, ML engineering separated from data science when deployment became a profession, and then generative AI emerged, bringing the AI engineer into visibility, which was minimal before 2022. The industry has not stabilized labels—GenAI Engineer, Prompt Engineer, or RAG Engineer coexist—and the gap is reflected in salaries: positions with similar missions can display very different ranges depending on the title. The size of the organization also weighs in: in a startup, one person may do everything under a single label; in a large company, these tasks are divided among several teams, sometimes five or more.
Preparing for the Interview: A Common Technical Foundation
Regardless of the title, the requirement rests on SQL, data preparation, and the ability to reason before coding. Interviews at companies like Meta, Uber, or Google combine coding related to recommendation systems, time series, and text processing, with theoretical questions on evaluation and communication. Proper problem definition, data leakage prevention, and the choice of relevant signals take precedence over memorizing algorithms. Preparation varies little from one title to another; a solid foundation and a clear discussion of trade-offs are expected for ML, AI, and LLM positions.
Brief IA — L'actualité IA en français
L'essentiel de l'actualité de l'intelligence artificielle, décrypté et expliqué chaque jour.