Python: Three Predictions to Understand Entropy
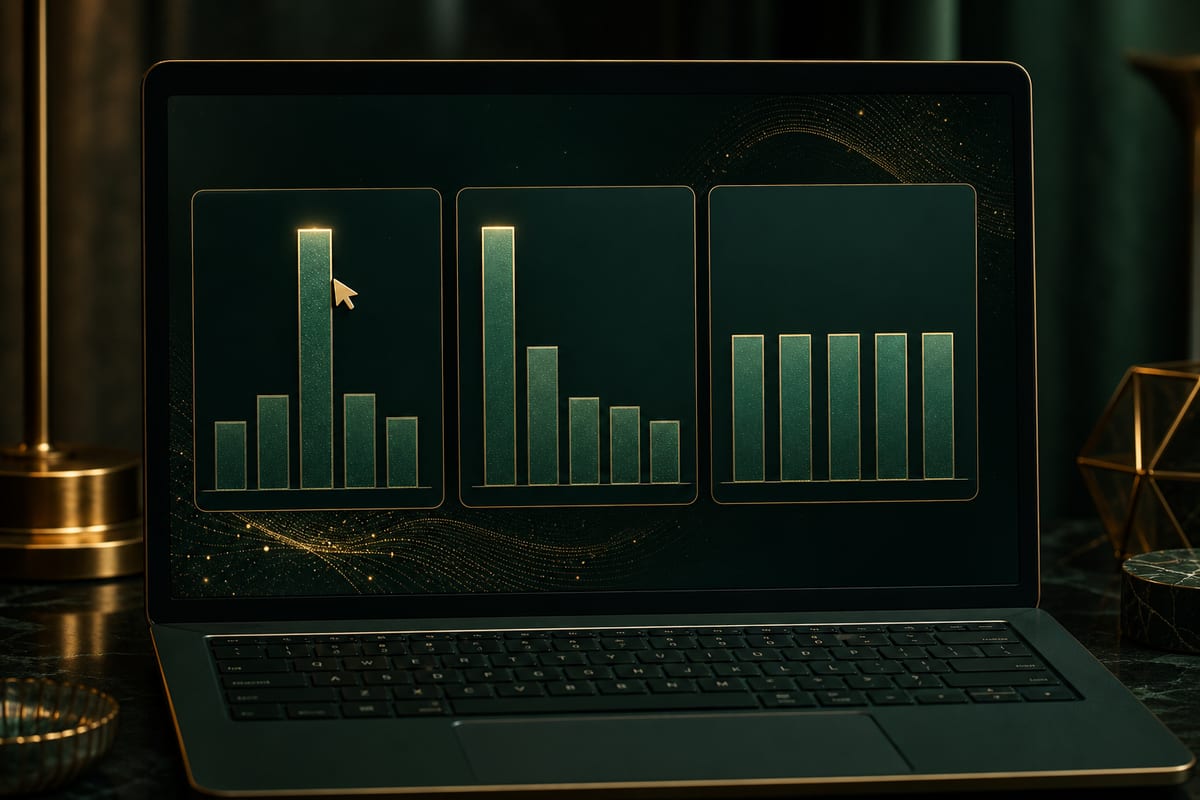
A Python example compares three simulated predictions to distinguish the entropy of a distribution from cross-entropy loss. No actual language model is loaded: the probabilities are predetermined.
A Confident Prediction Can Be Wrong
The vocabulary of the simulation includes five entries: apple, banana, cat, dog, elephant. The expected outcome is "cat," located at index 2. The target distribution, referred to as P, thus takes the form [0.0, 0.0, 1.0, 0.0, 0.0].
In the confident and correct case, the probabilities follow this order: [0.02, 0.03, 0.90, 0.03, 0.02]. The confident but incorrect case, on the other hand, favors "apple," with [0.80, 0.05, 0.05, 0.05, 0.05]. Finally, the uncertain case assigns the same probability to each entry: [0.20, 0.20, 0.20, 0.20, 0.20].
These assumptions are gathered in the Python dictionary models; they do not correspond to performance measured on real systems. For each, the calculation confronts the predicted distribution with P using cross-entropy.
Entropy Measures Uncertainty
Introduced by Claude Shannon in 1948, entropy quantifies the uncertainty associated with a probability distribution. Its definition is H(P) = −Σ P(x) log₂ P(x). When all outcomes have the same probability, this measure reaches its maximum; when a distribution concentrates more on certain outcomes, it decreases.
A fair die provides an example of maximum uncertainty. A die heavily favoring the 6, on the contrary, presents low entropy. For a text prediction, a spread-out distribution similarly reflects high uncertainty, while a probability almost entirely concentrated on "tatami" corresponds to low entropy.
The code explicitly distinguishes this measure from loss: shannon_entropy applies −Σ dist × log₂(dist + 1e-9), while cross_entropy applies −Σ true_dist × log₂(pred_dist + 1e-9). The first function focuses on the predicted distribution itself. The second also involves the target distribution.
Le brief IA que les pros lisent chaque soir
Les 7 actus IA du jour, décryptées en 5 min. Gratuit.
Inclus dès l'inscription : notre sélection des meilleurs guides & comparatifs IA.
Choisissez votre rythme
Gratuit · Pas de spam · Désabonnement en 1 clic
Training Favors the Expected Word
Language models produce their text in successive steps, rather than generating an entire response simultaneously. Before each output, their final layer assigns probabilities to the vocabulary elements, which typically includes tens of thousands of words. Entropy and cross-entropy connect this prediction mechanism to information theory.
For the sequence "the cat is sitting on the ...", the training example may impose "tatami" as the expected response. The target distribution then assigns 100% to this word and 0% to the others. It serves the role of a known label in machine learning; in the Python simulation, it is P that provides this input to the loss calculation.
The goal is not only to make a prediction less uncertain: cross-entropy confronts the proposed probabilities with this target. Its minimization gradually shifts the probability toward the expected word. Repeated over millions or billions of examples across many iterations, this learning allows the model to produce coherent responses.
Plotly Displays Probabilities on Hover
The illustration runs in a notebook or Python script, using NumPy for numerical operations and Plotly for interactive charts. It relies solely on the probability arrays defined in the code.
The graphs occupy one row and three columns, with a common vertical scale ranging from 0 to 1. The title of each panel indicates the scenario, entropy in bits, and loss, displayed with two decimal places. The "cat" bar appears in green, while the others are in blue, without a separate legend.
On hover, each bar reveals the relevant token, its probability expressed as a percentage with one decimal place, and an indication of whether or not it is the target.
Brief IA — L'actualité IA en français
L'essentiel de l'actualité de l'intelligence artificielle, décrypté et expliqué chaque jour.