Reducing LLM Latency: 7 Key Strategies
Le brief IA que les pros lisent chaque soir
Les 7 actus IA du jour, décryptées en 5 min. Gratuit.
Inclus dès l'inscription : notre sélection des meilleurs guides & comparatifs IA.
Choisis ton rythme
Gratuit · Pas de spam · Désabonnement en 1 clic
Managing Inference Latency
Large Language Models (LLMs) are transitioning from research to practical applications, presenting new challenges for engineering teams. Indeed, while designing a high-performing model is a complex task, making it accessible to users in real-time is a challenge of an entirely different magnitude.
In the field of generative AI, inference is the phase where a model, after being trained, processes a given input (the prompt) to produce a response. Inference latency refers to the time required for this process. Unlike traditional web applications where latency is often measured in milliseconds, that of LLMs can reach several seconds if not optimized, which can harm the user experience and lead to high computational costs.
To understand why a response may be slow, one must analyze the two distinct phases of LLM generation:
-
Pre-Filling Phase (Reading): The model processes the entire prompt at once, and this phase is limited by the available computational power. The longer the prompt, the more time-consuming this step becomes.
-
Decoding Phase (Writing): The model generates the response sequentially, one token at a time. Each new token requires the context of all previous tokens, which prevents parallelization and limits the process to the available memory bandwidth.
These two phases influence two key metrics for user experience: Time to First Token (TTFT), which measures the delay before the first word appears, and Time per Output Token (TPOT), which evaluates the speed of continuous generation.
1. Implementing Model Quantization
An LLM is essentially a vast collection of numerical weights, often stored in 16-bit floating-point format (FP16 or BF16). For example, a 70 billion parameter model in FP16 requires about 140 GB of VRAM to load, and moving this data across the GPU for each generated token creates a severe memory bandwidth bottleneck, directly increasing the TPOT.
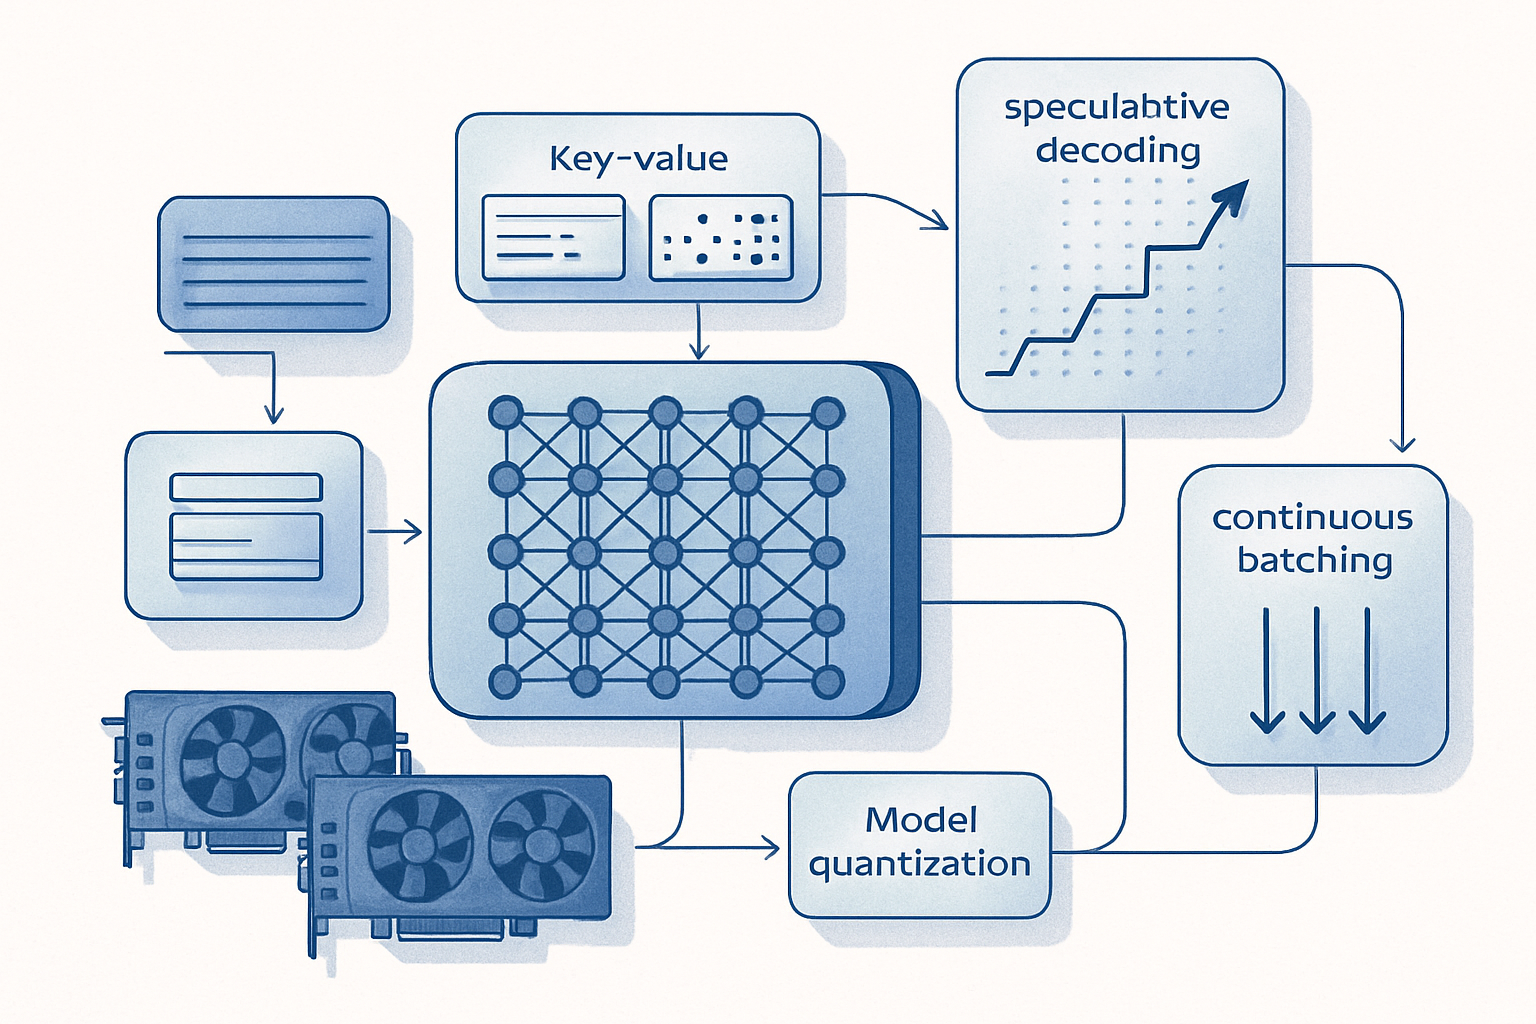
Quantization allows for compressing the model by converting weights from 16 bits to 8 bits (INT8) or 4 bits (INT4), significantly reducing the memory footprint. A model quantized to 4 bits moves in memory four times faster than an FP16 model, directly reducing decoding latency. The trade-off is a slight potential degradation in the model's reasoning quality, although modern techniques like Activation-Wise Quantization (AWQ) and GPTQ minimize this loss of precision.
2. Utilizing Key-Value Caching
LLMs rely on the Transformer architecture, which uses a self-attention mechanism. When a model generates token #100, it must understand how this token relates to tokens 1 through 99. Recalculating the mathematical relationships (the Keys and Values) for all previous tokens at each step is computationally expensive, and this is exactly the redundant work that the key-value (KV) cache eliminates.
The KV cache stores the Key and Value matrices of previously processed tokens in VRAM. When generating the next token, the model retrieves historical context from the cache and only calculates the mathematics for the most recent token. This reduces computation time and decreases the TPOT. The trade-off is memory cost: as the generated text becomes longer, the KV cache grows dynamically, consuming more VRAM. Balancing cache size against generation speed is a critical concern for any LLM system in production.
3. Leveraging Speculative Decoding
The most persistent bottleneck in LLM inference is the sequential nature of autoregressive generation. You cannot generate token #5 without knowing token #4, and this strict dependency makes naive parallelization impossible. Speculative decoding circumvents this by allowing models to write multiple words at once, using two models in tandem:
- A massive, slow "target" model (e.g., Llama-3-70B)
- A small, fast "draft" model (e.g., Llama-3-8B)
The process works as follows:
# PSEUDOCODE -- illustrative only, not a real framework API
draft_tokens = draft_model.generate(prompt, n=5)  # Practically instantaneous
accepted = target_model.verify(draft_tokens)       # Single parallel gateway
# If the draft is accurate, the 5 tokens are accepted
output_tokens.extend(accepted)
In practice, Hugging Face implements this by passing assistant_model=draft_model to the target model's .generate() call. The verification loop is handled internally. When the draft model is accurate, you completely bypass the sequential memory bottleneck, speeding up text generation by 2x to 3x without any loss in output quality under favorable conditions.
4. Transitioning to Continuous Batching
Traditional machine learning servers handle requests in static batches to maximize GPU utilization. If four requests arrive together, the server groups them, processes them in parallel, and returns the results. The problem: LLM outputs have highly variable lengths. If three requests finish in 100 tokens but one requires 1,000, the first three users wait idly for the longest request to complete.
Continuous batching (also known as iteration-level scheduling) fixes this. Instead of waiting for an entire batch to finish, the inference engine continuously injects new requests and evicts those that are completed at the token level. As soon as a short request finishes, the server immediately returns it and inserts a new user into that freed computation space, reducing both individual latency and overall server wait times.
5. Pruning and Distilling Your Models
While quantization reduces the size of existing weights, model pruning completely removes weights. Neural networks are inherently over-parameterized, and not all neurons contribute equally to every task. By identifying and eliminating the layers or attention heads that contribute the least to the model's performance, you physically reduce the architecture.
Knowledge distillation takes a different angle: training a smaller, faster "student" model to replicate the behavior of a larger "teacher" model. If you are using a 70 billion parameter model for a task like basic sentiment analysis or structured data extraction, the overhead is unnecessary. Distilling this capability into a purpose-built 8 billion parameter model can significantly reduce inference latency—potentially to tens of milliseconds on a modern GPU—while retaining the specific reasoning quality you need.
6. Deploying with Optimized Inference Engines
If you serve LLMs using the default .generate() function of a standard library, your latency will suffer. Standard libraries are designed for research flexibility and debugging ease, not for high-throughput, low-latency production service. To take speed seriously, deploy your models using a dedicated inference service framework. vLLM, Text Generation Inference (TGI) from Hugging Face, and TensorRT-LLM from NVIDIA are all designed for high-performance service: TGI is written in Rust and Python, vLLM uses Python with optimized C++/CUDA kernels, and TensorRT-LLM is implemented in C++ and CUDA.
These engines automatically implement:
-
PagedAttention: Intelligent management of non-contiguous memory for the KV cache.
-
Continuous batching: As described above, integrated into the service layer.
-
Optimized CUDA kernels: Hardware-level acceleration for Transformer operations.
Adopting one of these frameworks often significantly reduces both TTFT and TPOT with minimal changes to your model code.
7. Optimizing Context and Prompt Management
Engineering teams often overlook the most accessible way to reduce TTFT: sending less data to the model. In retrieval-augmented generation (RAG) pipelines, it is common to inject thousands of words of retrieved context into a prompt as a precaution, even when most of them are irrelevant. Each additional token in the prompt increases pre-filling computation time. Two targeted strategies help here.
-
Prompt compression: Use lighter natural language processing (NLP) models to summarize or extract only the most relevant sentences from your vector database before passing them to the LLM. This reduces pre-filling overhead without sacrificing response quality.
-
Prompt caching: If your application relies on a large static system prompt (like a 2,000-word set of behavioral instructions), modern APIs and inference engines allow you to cache the pre-filling state of this prompt. When a new user connects, the model avoids recalculating the system prompt and only processes the specific user request, directly reducing TTFT.
Stacking Optimizations in Practice
Reducing inference latency is rarely a matter of a single solution. It is a process of accumulating incremental improvements. A workflow using a model quantized in INT8, served via vLLM with continuous batching and accelerated by speculative decoding, will behave like a completely different application compared to an unoptimized baseline.
Speed always involves trade-offs around infrastructure costs, throughput ceilings, and engineering complexity. As you implement these approaches, you will need a structured way to evaluate your return on investment and ensure that speed gains do not quietly increase hosting bills.
Each of these seven approaches addresses a different level of the inference stack, from the weight level to prompt engineering. Addressing them systematically is the most reliable path to shipping fast, cost-effective generative AI applications.
Brief IA — L'actualité IA en français
L'essentiel de l'actualité de l'intelligence artificielle, décrypté et expliqué chaque jour.